# LoRA: adapt, save and merge low-rank updates

Phase 18: Post-training: SFT, LoRA, reward models and RLHF · about 105 minutes · CPU

## What you will be able to do

- Separate the frozen base from trainable adapters
- Understand initialization and the first gradient
- Verify the changed-condition exercise and explain the limits of this fixture.

## The problem

A trained dense layer already works, but the task changes. Can we fit the change while leaving the original weights untouched? We will first train a base, then learn and audit a low-rank update.

## The idea

LoRA adds a trainable low-rank correction to a frozen weight map. The base still participates in the forward pass while a smaller set of factors adapts the output. Shape convention and scaling determine how those paths combine.

## Separate the frozen path from the low-rank correction

Here the base matrix has shape $(6,4)$. With rank $r$, factors have shapes $(6,r)$ and $(r,4)$, so their product has the same shape as the base. The correction is scaled by $\alpha/r$ before addition.

In the fixture, the second factor starts at zero. The correction is initially zero; the first factor's initial gradient is also zero, while the second factor can receive a nonzero gradient. This is an informative initialization check rather than evidence that training is broken.

After training, compare separate-branch inference with merged weights using the same scaling. Freezing parameters does not mean their computation vanishes. The plot of factor gradients explains which path learns first; it does not imply every full-model adapter behaves identically.

### Frozen base plus a low-rank correction

**Predict:** If rank changes while alpha stays fixed, can you omit the scaling when merging?
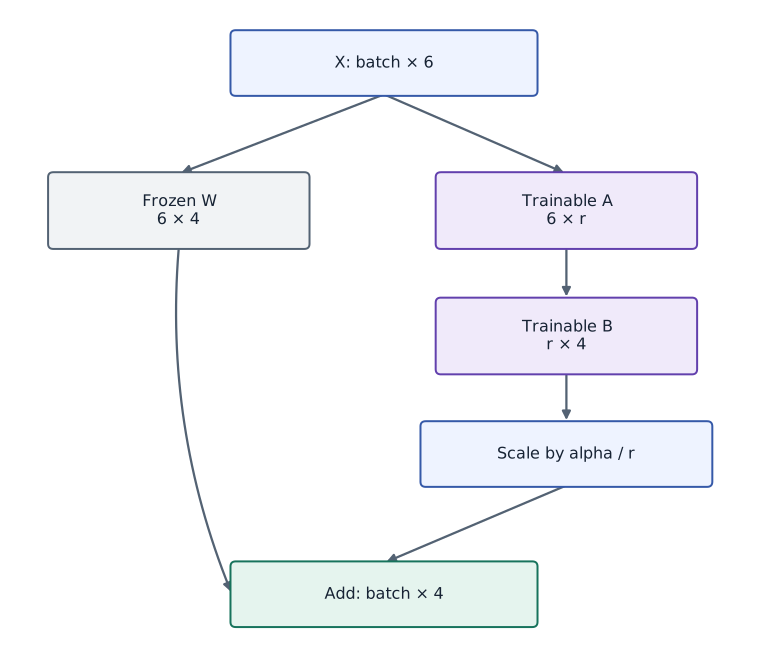
![Frozen base plus a low-rank correction](../figures/posttraining-02-mechanism.svg)

*Architecture and dataflow mechanism diagram.*

Input enters both branches. The base weight is frozen; A and B are trainable. Both paths return four features before addition. Include $\alpha/r$ when merging. These are forward-data arrows: gradients update adapter factors but not frozen base parameters.

### Pause and reason

If rank changes while alpha stays fixed, can you omit the scaling when merging?

<details><summary>Compare your reasoning</summary>

No. Merge the exact scaled correction used in forward computation. Otherwise the merged model computes a different function.

</details>

## Before coding: adapt a change, not an entire matrix

Begin with a base mapping that already works on a source task. The new task changes the output in a small number of directions. LoRA represents an added matrix through two smaller factors while preserving the base weights. Freezing the base protects those stored weights; it does not guarantee the adapted outputs retain the old behavior. That is why adaptation and retention need separate evaluation.

Trace dimensions for input width $d$, output width $k$, and rank $r$. The first factor compresses inputs into $r$ coordinates, and the second expands them into the output coordinates. The update matrix can have rank at most $r$, regardless of training time.

## Separate the frozen base from trainable adapters

For input-by-output weights $W_0$, let $A$ have shape $(d,r)$ and $B$ shape $(r,k)$. Compute the base output plus the scaled adapter output. Only the adapter tuple is passed to the gradient function. Keep a copy of $W_0$ and compare it exactly after training.

$$
Y=XW_0+\frac{\alpha}{r}XAB
$$

## Understand initialization and the first gradient

Initialize $A$ randomly and $B$ to zero. The initial adapter output is zero, so predictions match the base. At this first step the gradient with respect to $A$ is zero because it multiplies $B$; the gradient for $B$ can be nonzero. Initializing both factors to zero would block both gradients for this bilinear update.

## Derive the first-step asymmetry

Write the dense-layer output gradient as $G$, with the same batch-by-output shape as the prediction. Let $s=\alpha/r$. The two derivatives below explain initialization. When $B=0$, the first derivative vanishes, while the second can be nonzero if $A$ is random. After one update to $B$, both factors may learn. If both factors start at zero, both gradients vanish and training stalls.

This is a property of the bilinear parameterization, not a JAX bug. Inspect factor norms and individual gradients before changing the learning rate.

$$
\nabla_A L=sX^\top GB^\top,\qquad \nabla_B L=sA^\top X^\top G
$$

## Use rank to predict a failure before training

A rank-one update can represent one independent output-change direction. Consider an ideal update with singular values $3$ and $1$. Any rank-one approximation leaves at least squared Frobenius error $1$; increasing optimization steps cannot remove that rank constraint. This matrix-space statement translates into prediction error only under assumptions about the input distribution. The exercise uses identity inputs so that distinction is visible.

Our main target was constructed as a rank-one update, so near-zero training error is expected. A convincing study compares several ranks on a harder held-out task and reports trainable parameters, optimizer memory, activation memory and measured runtime separately.

## Count the right kind of savings

The fixture has $6\times4=24$ base weights and rank $1$, giving $6+4=10$ trainable adapter scalars. The base remains resident. Real memory includes gradients, optimizer state, activations and runtime buffers. A low-bit frozen base plus adapters also needs a quantization policy and supported kernels; this lab does not implement QLoRA.

## Merge only under an explicit serving contract

Without adapter dropout, an inference merge computes $W_{\mathrm{merged}}=W_0+(\alpha/r)AB$. Check outputs on changed inputs before deleting or replacing anything. Keep the unmerged base, adapter and scaling metadata; a second accidental merge adds the update twice. Packed or quantized bases require dequantization/requantization rules rather than a blind in-place add.

## Save the adaptation identity

An adapter artifact needs the base checkpoint hash, target module names, rank, alpha, dtype and exact factor arrays. Match all of these on load. Compare the adapted task and original task separately; low rank does not prevent forgetting, and this rank-one teacher does not predict the rank required by a real task.

## Make an adapter artifact reproducible

Save the exact base identity, target layer names, tensor orientation, rank, scaling, factor dtype and adapter weights. Reconstruct the unmerged computation before testing a merge. A rank-two adapter with $\alpha=3$ requires scale $1.5$; forgetting that scale may go unnoticed in rank-one examples where it equals one.

Merging is exact algebraically for this dense layer, subject to floating-point rounding. Quantized bases, packed layouts and adapter dropout need additional contracts. Retain original artifacts, compare changed inputs after reload, and reject applying the same update twice. Keep a source-task metric alongside the new task before claiming that adaptation preserved useful behavior.

## 1. Define the frozen-plus-adapter forward pass

Create main.py in your activated course environment. Paste this block, then run python main.py; function definitions alone print nothing.

```python
# Step 1 — 1. Define the frozen-plus-adapter forward pass: The base is an input to the forward pass but is not in the adapter...
import jax
import jax.numpy as jnp
import numpy as np

def lora_forward(x, base, a, b, alpha=1.0):
    rank = a.shape[1]
    return x @ base + (alpha / rank) * (x @ a @ b)
```

The base is an input to the forward pass but is not in the adapter tuple differentiated by loss.

## 2. Train a base, freeze it and initialize the adapter

Append this block to main.py and run python main.py again. Keep the earlier blocks above it.

```python
# Step 2 — 2. Train a base, freeze it and initialize the adapter: This step includes the source-task training.
x = jnp.asarray(np.random.default_rng(4).normal(size=(24, 6)), jnp.float32)
# Construct and reshape `source_w` into the target tensor dimensions.
source_w = jnp.arange(24, dtype=jnp.float32).reshape(6, 4) / 40
base = jnp.zeros_like(source_w)
# Differentiate the objective to obtain `base_step` via automatic differentiation.
base_step = jax.jit(jax.grad(lambda w: jnp.mean((x @ w - x @ source_w) ** 2)))
for _ in range(150):
    base = base - 0.15 * base_step(base)
assert float(jnp.mean((x @ base - x @ source_w) ** 2)) < 1e-4
# Convert `frozen` to a host NumPy array for inspection or verification.
frozen = np.asarray(base).copy()
u = jnp.array([[0.2], [-0.3], [0.1], [0.2], [-0.1], [0.4]])
v = jnp.array([[0.5, -0.2, 0.3, 0.1]])
# Perform matrix / vector contraction (`@`) to compute `target`.
target = x @ (base + u @ v)
# Initialize explicit deterministic PRNG key `a`.
a = jax.random.normal(jax.random.key(4), (6, 1)) * 0.1
# Allocate initialized array `b` with the specified shape and dtype.
b = jnp.zeros((1, 4))
params = (a, b)
loss = lambda ab: jnp.mean((lora_forward(x, base, *ab, alpha=1.0) - target) ** 2)
# Evaluate both scalar loss and parameter gradients in one pass (`step`).
step = jax.jit(jax.value_and_grad(loss))
history = []
initial_grads = step(params)[1]
# Allocate initialized array `` with the specified shape and dtype.
np.testing.assert_array_equal(initial_grads[0], np.zeros((6, 1)))
assert np.linalg.norm(initial_grads[1]) > 0
```

This step includes the source-task training. Inspect the initial factor gradients: A has zero gradient and B has a nonzero one.

## 3. Adapt and verify the serving merge

Append this block to main.py and run python main.py again. Keep the earlier blocks above it.

```python
# Step 3 — 3. Adapt and verify the serving merge: The reference target has rank one by construction.
for _ in range(250):
    value, g = step(params)
    history.append(float(value))
    # Transform every leaf of the parameter PyTree (`params`).
    params = jax.tree.map(lambda a, b: a - 0.4 * b, params, g)

a, b = params
assert history[-1] < history[0] * 0.02
# Execute `np.testing.assert_array_equal(base, frozen)`
np.testing.assert_array_equal(base, frozen)
merged = base + a @ b
np.testing.assert_allclose(
    lora_forward(x, base, a, b), x @ merged, rtol=1e-5, atol=1e-6
)
print(
    'LoRA initial/final:',
    history[0],
    history[-1],
    '; trainable:',
    a.size + b.size,
    'base:',
    base.size,
)
```

The reference target has rank one by construction. Exact base equality and changed-input merge checks answer different questions from adaptation loss.

## Run the example

```python
# Step 1 — 1. Define the frozen-plus-adapter forward pass: The base is an input to the forward pass but is not in the adapter...
import jax
import jax.numpy as jnp
import numpy as np

def lora_forward(x, base, a, b, alpha=1.0):
    rank = a.shape[1]
    return x @ base + (alpha / rank) * (x @ a @ b)

# Step 2 — 2. Train a base, freeze it and initialize the adapter: This step includes the source-task training.
x = jnp.asarray(np.random.default_rng(4).normal(size=(24, 6)), jnp.float32)
# Construct and reshape `source_w` into the target tensor dimensions.
source_w = jnp.arange(24, dtype=jnp.float32).reshape(6, 4) / 40
base = jnp.zeros_like(source_w)
# Differentiate the objective to obtain `base_step` via automatic differentiation.
base_step = jax.jit(jax.grad(lambda w: jnp.mean((x @ w - x @ source_w) ** 2)))
for _ in range(150):
    base = base - 0.15 * base_step(base)
assert float(jnp.mean((x @ base - x @ source_w) ** 2)) < 1e-4
# Convert `frozen` to a host NumPy array for inspection or verification.
frozen = np.asarray(base).copy()
u = jnp.array([[0.2], [-0.3], [0.1], [0.2], [-0.1], [0.4]])
v = jnp.array([[0.5, -0.2, 0.3, 0.1]])
# Perform matrix / vector contraction (`@`) to compute `target`.
target = x @ (base + u @ v)
# Initialize explicit deterministic PRNG key `a`.
a = jax.random.normal(jax.random.key(4), (6, 1)) * 0.1
# Allocate initialized array `b` with the specified shape and dtype.
b = jnp.zeros((1, 4))
params = (a, b)
loss = lambda ab: jnp.mean((lora_forward(x, base, *ab, alpha=1.0) - target) ** 2)
# Evaluate both scalar loss and parameter gradients in one pass (`step`).
step = jax.jit(jax.value_and_grad(loss))
history = []
initial_grads = step(params)[1]
# Allocate initialized array `` with the specified shape and dtype.
np.testing.assert_array_equal(initial_grads[0], np.zeros((6, 1)))
assert np.linalg.norm(initial_grads[1]) > 0

# Step 3 — 3. Adapt and verify the serving merge: The reference target has rank one by construction.
for _ in range(250):
    value, g = step(params)
    history.append(float(value))
    # Transform every leaf of the parameter PyTree (`params`).
    params = jax.tree.map(lambda a, b: a - 0.4 * b, params, g)

a, b = params
assert history[-1] < history[0] * 0.02
# Execute `np.testing.assert_array_equal(base, frozen)`
np.testing.assert_array_equal(base, frozen)
merged = base + a @ b
np.testing.assert_allclose(
    lora_forward(x, base, a, b), x @ merged, rtol=1e-5, atol=1e-6
)
print(
    'LoRA initial/final:',
    history[0],
    history[-1],
    '; trainable:',
    a.size + b.size,
    'base:',
    base.size,
)
```

Expected: The trained base stays unchanged; 10 adapter scalars fit the rank-one change and merge equivalently.

## LoRA: adapt, save and merge low-rank updates — recorded experiment

**Predict:** Which initial adapter-gradient bar is zero, and why can training still begin?

![LoRA: adapt, save and merge low-rank updates — recorded experiment](../figures/posttraining-02.svg)

**Recorded CPU computation**

### Read the figure

The plot is adaptation MSE before each update, falling from about $0.044$ to below $10^{-6}$. It does not include the preceding base-training run. The target update was constructed to have rank one, so this is an achievable representation test rather than a universal LoRA performance claim.

The second panel compares the two initial factor-gradient norms. The zero-height A bar is expected because B starts at zero; the positive B bar shows the update has a route to begin learning. After B changes, A can receive gradient. These are initial gradients while the first panel spans the full adaptation run. The all-zero initialization experiment predicts two zero bars and nonzero loss, exposing a stalled parameterization.

### Connect it to the computation

The first adapter update affects B; later updates can train both factors. The unchanged-base assertion, reloaded adapter and new-input merge comparison are separate evidence from the falling training line.

```python
# Compute figure data for: LoRA: adapt, save and merge low-rank updates — recorded experiment
visual_data={'kind':'line','xlabel':'completed parameter updates before measurement','ylabel':'adaptation MSE (squared output units)','series':[{'label':'recorded CPU training loss','x':list(range(len(history))),'y':history}]}
for panel in visual_data.get('panels',[visual_data]):
    panel['x']=panel['series'][0]['x']

extra_panel={'kind':'bar','x':[0,1],'labels':['factor A','factor B'],'series':[{'label':'initial gradient norm','y':[float(jnp.linalg.norm(initial_grads[0])),float(jnp.linalg.norm(initial_grads[1]))]}],'xlabel':'trainable factor','ylabel':'gradient L2 norm','title':'Why the first update changes only B'}
visual_data={"panels":[*visual_data.get("panels",[visual_data]),extra_panel]}
```

## Recorded reference execution

CPU run: 2026-10-20T10:52:13.228766+00:00. JAX 0.9.2.

```text
LoRA initial/final: 0.043869297951459885 2.466217665642034e-07 ; trainable: 10 base: 24
Both zero factors produce zero first gradients.
Both LoRA factor gradients match the matrix-calculus oracle at alpha/r = 1.5.
Adapter round trip and merge checked.
New-input merge passes; accidental double merge changes outputs.
Nonunit scaling passes; best rank-one identity-input MSE is 0.25.
PASS: posttraining-02

```

## Show why two zero factors cannot start learning

**Predict before running:** If both factors start at zero, can this first-order update move either one?

```python
# Experiment — Show why two zero factors cannot start learning: Each factor’s derivative contains the other factor.
zero = (jnp.zeros_like(a), jnp.zeros_like(b))
# Differentiate the objective to obtain `zero_grad` via automatic differentiation.
zero_grad = jax.grad(loss)(zero)
assert all(
    np.array_equal(np.asarray(g), np.zeros(g.shape)) for g in zero_grad
)
print('Both zero factors produce zero first gradients.')
```

**Expected:** Both factor gradients are exactly zero.

Each factor’s derivative contains the other factor. Randomizing one and zeroing the other preserves the initial base output without blocking the whole update.

## Check both factor gradients with matrix calculus

**Predict before running:** At nonzero factors, will the two matrix-gradient formulas agree with autodiff including nonunit alpha?

```python
# Experiment — Check both factor gradients with matrix calculus: Nonzero factors exercise both gradient paths, while nonunit...
rng = np.random.default_rng(14)
# Create device-backed JAX array `a_probe`.
a_probe = jnp.asarray(rng.normal(size=(6, 2)) * 0.1, jnp.float32)
# Create device-backed JAX array `b_probe`.
b_probe = jnp.asarray(rng.normal(size=(2, 4)) * 0.1, jnp.float32)
scale = 3.0 / 2
# Evaluate the compound expression for `output_gradient`.
output_gradient = (
    2 * (lora_forward(x, base, a_probe, b_probe, 3.0) - target) / target.size
)
# Perform matrix / vector contraction (`@`) to compute `expected_a`.
expected_a = scale * x.T @ output_gradient @ b_probe.T
# Perform matrix / vector contraction (`@`) to compute `expected_b`.
expected_b = scale * a_probe.T @ x.T @ output_gradient
# Differentiate the objective to obtain `(actual_a, actual_b)` via automatic differentiation.
actual_a, actual_b = jax.grad(
    lambda aa, bb: jnp.mean(
        (lora_forward(x, base, aa, bb, 3.0) - target) ** 2
    ),
    argnums=(0, 1),
)(a_probe, b_probe)
np.testing.assert_allclose(actual_a, expected_a, atol=1e-6)
np.testing.assert_allclose(actual_b, expected_b, atol=1e-6)
print('Both LoRA factor gradients match the matrix-calculus oracle at alpha/r = 1.5.')
```

**Expected:** Both factor derivatives match the independent output-gradient calculation.

Nonzero factors exercise both gradient paths, while nonunit scaling catches a factor missing from the derivative. The separate all-zero experiment demonstrates the initialization failure.

## Make it yours

Save both adapter factors and their rank/scaling metadata, reload them and check merged versus unmerged predictions.

### How to write this exercise — Step-by-step recipe & starter scaffold

**Key functions & syntax to use:**
- `jnp.allclose(actual, expected, rtol=..., atol=...)` — Checks that two arrays match elementwise within floating-point tolerance.

**Step-by-step implementation plan:**
1. Create an isolated temporary directory to run and inspect artifacts safely:
2. Convert `` to a host NumPy array for inspection or verification.
3. Enter `np.load(path, allow_pickle=False)` context block:
4. Check tensor shape invariant: `int(z['rank']) == z['a'].shape[1]`

**Starter code scaffold (fill in the TODOs):**

```python
# Exercise solution: Save both adapter factors and their rank/scaling metadata, reload them...
import tempfile
from pathlib import Path

# Create an isolated temporary directory to run and inspect artifacts safely:
with tempfile.TemporaryDirectory() as folder:
    path = Path(...)  # TODO: compute path
    # Convert `` to a host NumPy array for inspection or verification.
    np.savez(
        path,
        a = np.asarray(...)  # TODO: compute a
        b = np.asarray(...)  # TODO: compute b
        alpha = np.array(...)  # TODO: compute alpha
        rank = np.array(...)  # TODO: compute rank
    )
    # Enter `np.load(path, allow_pickle=False)` context block:
    with np.load(path, allow_pickle=False) as z:
        # Check tensor shape invariant: `int(z['rank']) == z['a'].shape[1]`
        assert int(z['rank'])  # TODO: complete assertion check
        np.testing.assert_allclose(
            lora_forward(x, base, z['a'], z['b'], float(z['alpha'])),
            x @ merged,
            atol = ...  # TODO: compute atol
            rtol = ...  # TODO: compute rtol
        )
print('Adapter round trip and merge checked.')
```

<details><summary>Reference solution</summary>

```python
# Exercise solution: Save both adapter factors and their rank/scaling metadata, reload them...
import tempfile
from pathlib import Path

# Create an isolated temporary directory to run and inspect artifacts safely:
with tempfile.TemporaryDirectory() as folder:
    path = Path(folder) / 'adapter.npz'
    # Convert `` to a host NumPy array for inspection or verification.
    np.savez(
        path,
        a=np.asarray(a),
        b=np.asarray(b),
        alpha=np.array(1.0),
        rank=np.array(1),
    )
    # Enter `np.load(path, allow_pickle=False)` context block:
    with np.load(path, allow_pickle=False) as z:
        # Check tensor shape invariant: `int(z['rank']) == z['a'].shape[1]`
        assert int(z['rank']) == z['a'].shape[1]
        np.testing.assert_allclose(
            lora_forward(x, base, z['a'], z['b'], float(z['alpha'])),
            x @ merged,
            atol=1e-6,
            rtol=1e-5,
        )
print('Adapter round trip and merge checked.')
```

</details>

## Check the merge on new inputs

**Transfer**

Draw a new input batch and compare the merged layer with the adapter path.

<details><summary>Hint</summary>

The equivalence is algebraic, so a new input should still agree.

</details>

### How to write: Check the merge on new inputs — Step-by-step recipe & starter scaffold

**Key functions & syntax to use:**
- `jnp.allclose(actual, expected, rtol=..., atol=...)` — Checks that two arrays match elementwise within floating-point tolerance.

**Step-by-step implementation plan:**
1. Set up the changed input or configuration parameters requested in the prompt.
2. Run the target function or transformation and assert that the output matches your prediction.

**Starter code scaffold (fill in the TODOs):**

```python
# Check the merge on new inputs (Transfer): The second check detects an operational merge error that...
new_x = jnp.asarray(...)  # TODO: compute new_x
np.testing.assert_allclose(
    lora_forward(new_x, base, a, b), new_x @ merged, atol=1e-6, rtol=1e-5
)
assert np.linalg.norm(np.asarray(new_x @ (base + 2 * a @ b) - new_x @ merged))  # TODO: complete assertion check
print('New-input merge passes; accidental double merge changes outputs.')
```

<details><summary>Reference solution and reasoning</summary>

```python
# Check the merge on new inputs (Transfer): The second check detects an operational merge error that...
new_x = jnp.asarray(np.random.default_rng(91).normal(size=(7, 6)), jnp.float32)
np.testing.assert_allclose(
    lora_forward(new_x, base, a, b), new_x @ merged, atol=1e-6, rtol=1e-5
)
assert np.linalg.norm(np.asarray(new_x @ (base + 2 * a @ b) - new_x @ merged)) > 1e-3
print('New-input merge passes; accidental double merge changes outputs.')
```

The second check detects an operational merge error that training loss alone would not reveal.

</details>

## Test nonunit scaling and an impossible rank-one target

**Challenge**

Check merge equivalence at rank two with alpha three. Then use identity inputs and a diagonal target with singular values three and one to calculate the best rank-one residual.

<details><summary>Hint</summary>

Use an independent singular-value decomposition for the rank bound, and divide alpha by rank in both serving paths.

</details>

### How to write: Test nonunit scaling and an impossible rank-one target — Step-by-step recipe & starter scaffold

**Key functions & syntax to use:**
- `x.sum(axis=...) / x.mean(axis=..., keepdims=...)` — Reduces values along the named `axis` (the axis you name is collapsed unless `keepdims=True`).
- `jnp.allclose(actual, expected, rtol=..., atol=...)` — Checks that two arrays match elementwise within floating-point tolerance.

**Step-by-step implementation plan:**
1. Create device-backed JAX array `a2`.
2. Create device-backed JAX array `b2`.
3. Perform matrix / vector contraction (`@`) to compute `rank_one`.
4. Execute `np.testing.assert_allclose(np.sum((target_update - rank_one) ** 2), 1.0)`.
5. Construct an identity matrix ``.

**Starter code scaffold (fill in the TODOs):**

```python
# Test nonunit scaling and an impossible rank-one target (Challenge): The residual predicts a capacity limit independently of an...
rng = np.random.default_rng(...)  # TODO: compute rng
# Create device-backed JAX array `a2`.
a2 = jnp.asarray(...)  # TODO: compute a2
# Create device-backed JAX array `b2`.
b2 = jnp.asarray(...)  # TODO: compute b2
np.testing.assert_allclose(
    lora_forward(x, base, a2, b2, alpha = ...  # TODO: compute lora_forward(x, base, a2, b2, alpha
    x @ (base + 1.5 * a2 @ b2),
    rtol = ...  # TODO: compute rtol
    atol = ...  # TODO: compute atol
)
target_update = np.diag(...)  # TODO: compute target_update
u_s, s_s, v_s = np.linalg.svd(...)  # TODO: compute u_s, s_s, v_s
# Perform matrix / vector contraction (`@`) to compute `rank_one`.
rank_one = ...  # TODO: compute rank_one
# Execute `np.testing.assert_allclose(np.sum((target_update - rank_one) ** 2), 1.0)`.
np.testing.assert_allclose(np.sum((target_update - rank_one) ** 2), 1.0)
# Construct an identity matrix ``.
np.testing.assert_allclose(
    np.mean((np.eye(2) @ target_update - np.eye(2) @ rank_one) ** 2), 0.25
)
print('Nonunit scaling passes; best rank-one identity-input MSE is 0.25.')
```

<details><summary>Reference solution and reasoning</summary>

```python
# Test nonunit scaling and an impossible rank-one target (Challenge): The residual predicts a capacity limit independently of an...
rng = np.random.default_rng(8)
# Create device-backed JAX array `a2`.
a2 = jnp.asarray(rng.normal(size=(6, 2)), jnp.float32)
# Create device-backed JAX array `b2`.
b2 = jnp.asarray(rng.normal(size=(2, 4)), jnp.float32)
np.testing.assert_allclose(
    lora_forward(x, base, a2, b2, alpha=3.0),
    x @ (base + 1.5 * a2 @ b2),
    rtol=1e-5,
    atol=2e-6,
)
target_update = np.diag([3.0, 1.0])
u_s, s_s, v_s = np.linalg.svd(target_update)
# Perform matrix / vector contraction (`@`) to compute `rank_one`.
rank_one = (u_s[:, :1] * s_s[:1]) @ v_s[:1]
# Execute `np.testing.assert_allclose(np.sum((target_update - rank_one) ** 2), 1.0)`.
np.testing.assert_allclose(np.sum((target_update - rank_one) ** 2), 1.0)
# Construct an identity matrix ``.
np.testing.assert_allclose(
    np.mean((np.eye(2) @ target_update - np.eye(2) @ rank_one) ** 2), 0.25
)
print('Nonunit scaling passes; best rank-one identity-input MSE is 0.25.')
```

The residual predicts a capacity limit independently of an optimizer. The nonunit-alpha case catches a scaling bug that the main rank-one demonstration would miss.

</details>

## Check your understanding

Does LoRA require updating the base weights during adapter training?

1. No. The base is frozen; the selected adapter parameters receive updates.
2. Yes, because initializing factor $B=0$ blocks all gradients until the base matrix moves.
3. No, and freezing the base weights guarantees that adapted outputs cannot forget the source task.

<details><summary>Answer and explanation</summary>

No. The base is frozen; the selected adapter parameters receive updates.

Freeze ownership should be checked in code, not inferred from an adapter-shaped parameter name.

</details>

## Diagnose the result

If neither factor moves, inspect initialization. If merged predictions drift, check factor orientation, rank scaling, dropout, base identity and accidental repeated merges.

## Carry forward

- Initialize one LoRA factor randomly and the other to zero so the initial correction is zero while the zero-initialized factor still receives a nonzero first gradient.
- Preserve the base checkpoint identity, rank $r$, and scale $\alpha/r$ in saved adapter artifacts, and verify merged weights $W_0 + (\alpha/r)AB$ against unmerged inference on new inputs.

## Keep your evidence

Keep base-training evidence, unchanged base arrays, adapter factors/rank/alpha, initial-gradient checks and reloaded/new-input merge parity.

Save your predictions, modified code, terminal outputs, and reasoning in your engineering portfolio.

## Primary references

- [LoRA](https://arxiv.org/abs/2106.09685)

