# Direct preference optimization and reference-corrected margins

Phase 18: Post-training: SFT, LoRA, reward models and RLHF · about 105 minutes · CPU

## What you will be able to do

- Compare chosen and rejected response log probabilities
- Subtract the reference preference
- Verify the changed-condition exercise and explain the limits of this fixture.

## The problem

Can we train on chosen/rejected responses without collecting fresh reward-model rollouts? DPO provides a different training objective. We will work through the reference correction and compare its bookkeeping with the preceding RLHF loop.

## The idea

DPO uses chosen/rejected preferences and a fixed reference to optimize a policy directly. It compares policy log-probability differences with reference differences. This training step does not require an explicit reward-model call or on-policy rollout.

## A better relative margin need not raise chosen probability

Suppose chosen probability falls from $0.4$ to $0.3$ while rejected probability falls from $0.2$ to $0.1$. The chosen-to-rejected ratio rises from $2$ to $3$, even though the chosen probability decreased. Relative preference improvement and absolute likelihood improvement are different claims.

The reference corrects that log-ratio margin, and beta scales it in the loss. Keep the reference checkpoint and any cached reference probabilities bound to the same examples and preprocessing.

Read the margin plot alongside individual probabilities when diagnosing behavior. A growing training margin is separate from held-out preference quality or generation quality. The categorical fixture teaches the objective; sequence integration also needs token masking and log-probability aggregation checks.

### DPO corrects a policy margin with a reference

**Predict:** What extra evidence would you inspect before claiming a DPO update makes chosen responses more likely?
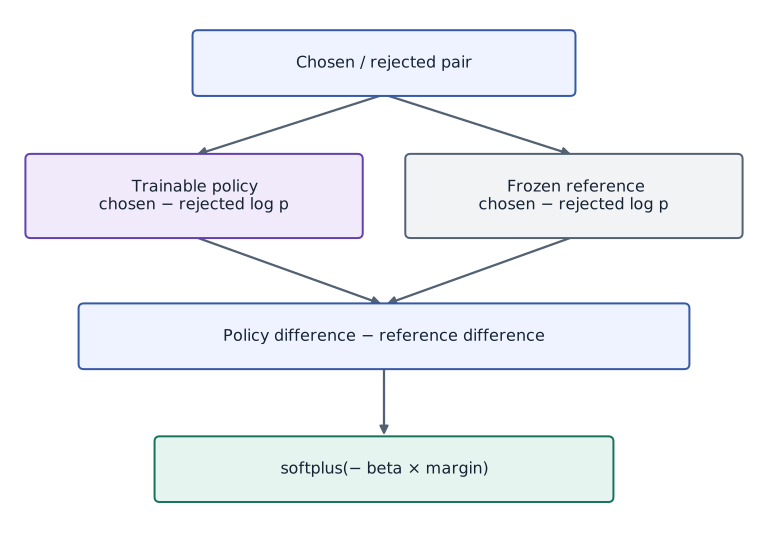
![DPO corrects a policy margin with a reference](../figures/posttraining-05-mechanism.svg)

*Architecture and dataflow mechanism diagram.*

Both models score the same chosen/rejected pair. Their log-probability differences form a reference-corrected margin, which beta scales before the stable preference loss. The reference is frozen. There is no reward-model call or on-policy rollout in this step.

### Pause and reason

What extra evidence would you inspect before claiming a DPO update makes chosen responses more likely?

<details><summary>Compare your reasoning</summary>

Inspect chosen probabilities or sequence log probabilities directly under a fixed measurement contract. A relative margin alone is distinct from that absolute change.

</details>

## Before coding: compare changes in preference, not raw scores

Consider a prompt with one chosen and one rejected response. The reference already prefers one of them to some degree. DPO asks how the current policy changes that relative preference. Write four log probabilities: current chosen, current rejected, reference chosen and reference rejected. Take a within-model difference first, then subtract the reference difference.

When current and reference models are identical, both differences cancel even if neither response has high probability. The loss starts at $\log2$. This cancellation is a precise implementation check, not evidence that the initial model is indifferent between the two responses.

## Compare chosen and rejected response log probabilities

Both responses belong to the same prompt. Compute their sequence log probabilities under current and reference policies. Exclude prompt and padding tokens consistently. Keep lengths, tokenization and special-token rules visible because they determine the probability of the represented response.

## Subtract the reference preference

The reference-corrected margin subtracts what the reference already preferred. At initialization when current policy equals reference, the corrected margin is zero and the loss is $\log2$, even if the reference assigns unequal response probabilities.

$$
L_{\mathrm{DPO}}=\mathbb E\left[\operatorname{softplus}\!\left(-\beta\left[\log\frac{\pi_\theta(y^+|x)}{\pi_\theta(y^-|x)}-\log\frac{\pi_{\mathrm{ref}}(y^+|x)}{\pi_{\mathrm{ref}}(y^-|x)}\right]\right)\right]
$$

## Work through a numeric margin and its gradient

Suppose current chosen/rejected log probabilities are $-2$ and $-4$, while reference values are $-3$ and $-4$. The current gap is $2$, the reference gap is $1$, and the corrected margin is $1$. With $\beta=0.3$, the loss is $\log(1+e^{-0.3})$, about $0.554$. Reversing chosen and rejected flips the corrected margin.

Let $m$ denote the corrected margin. Its derivative below is negative for finite $m$, so gradient descent increases the chosen-versus-rejected gap on this pair. The underlying model shares parameters across many responses, so this local pressure does not guarantee every chosen response’s absolute probability rises.

$$
\frac{\partial L}{\partial m}=-\beta\,\sigma(-\beta m)
$$

## A rising preference ratio can hide falling chosen probability

Imagine reference probabilities $[0.4,0.4,0.2]$ for chosen, rejected and another response. A new policy $[0.3,0.1,0.6]$ lowers the chosen probability but lowers the rejected probability even more. The chosen/rejected ratio grows from one to three, so the DPO loss improves for this comparison.

Track chosen and rejected sequence log probabilities separately, not only the margin. Also evaluate useful task behavior, response length and diversity on held-out prompts. Pairwise training is a relative objective; it does not directly specify the probability allocated to every unpaired response.

## Keep the algorithm distinction visible

This loop updates from fixed preference pairs; it has no separately trained reward model or on-policy rollout stage. That does not make it PPO with a different optimizer. Both methods need a base/reference identity and reliable preference data, but their estimators, data freshness and failure modes differ.

## Treat beta and length as part of the objective

Beta scales the corrected margin and changes update behavior; it is not interchangeable with every explicit KL coefficient in a PPO implementation. Response sums and response means also differ. Make comparisons under a declared objective and evaluation protocol instead of selecting hyperparameters from a training-loss curve alone.

## Evaluate beyond chosen-pair fit

Frozen-pair optimization can overfit or reduce useful response diversity. Retain held-out prompts, independent task metrics and reviewed outputs; inspect slices rather than only average preference accuracy. Synthetic action preferences establish an objective implementation test, not an aligned language model.

## Carry sequence bookkeeping and reference identity into a real model

For language responses, add log probabilities over valid answer and end tokens while conditioning on the prompt. Exclude padding and prompt targets consistently. A mean over response length changes the objective: two equally likely tokens have twice the negative log probability of one. Decide which objective you intend rather than introducing normalization as an innocent convenience.

Reference caches must bind prompt text, chosen/rejected ordering, tokenizer, chat template, mask and checkpoint revision. A frozen array can still be wrong if its examples were reordered. Split prompt groups before fitting, compare fixed decoding on held-out tasks, and retain the actual reference artifact so a later run can reproduce the correction. This categorical lab supplies objective checks, not the sequence trainer.

## 1. Define the reference-corrected pair objective

Create main.py in your activated course environment. Paste this block, then run python main.py; function definitions alone print nothing.

```python
# Step 1 — 1. Define the reference-corrected pair objective: The reference correction is detached, while current policy log...
import jax
import jax.numpy as jnp
import numpy as np

# Define `dpo_loss(policy_logps, reference_logps, chosen, rejected...)` to evaluate the objective and its automatic derivatives:
def dpo_loss(policy_logps, reference_logps, chosen, rejected, beta=0.2):
    margin = (policy_logps[chosen] - policy_logps[rejected]) - jax.lax.stop_gradient(
        reference_logps[chosen] - reference_logps[rejected]
    )
    return jnp.mean(jax.nn.softplus(-beta * margin))
```

The reference correction is detached, while current policy log probabilities remain differentiable.

## 2. Freeze reference probabilities and comparison IDs

Append this block to main.py and run python main.py again. Keep the earlier blocks above it.

```python
# Step 2 — 2. Freeze reference probabilities and comparison IDs: The initial policy equals a nonuniform reference.
reference = jax.nn.log_softmax(jnp.array([0.2, 0.0, -0.2]))
chosen = jnp.array([0, 0, 1])
rejected = jnp.array([1, 2, 2])
theta = jnp.array([0.2, 0.0, -0.2])
history = []
# Evaluate numerically stable log-space cross-entropy/likelihood (`loss`).
loss = lambda theta: dpo_loss(
    jax.nn.log_softmax(theta), reference, chosen, rejected, 0.3
)
# Differentiate the objective to obtain `step` via automatic differentiation.
step = jax.jit(jax.value_and_grad(loss))
np.testing.assert_allclose(loss(theta), np.log(2), atol=1e-6)
```

The initial policy equals a nonuniform reference. Predict the corrected margin and initial loss before continuing.

## 3. Fit the policy and test cancellation

Append this block to main.py and run python main.py again. Keep the earlier blocks above it.

```python
# Step 3 — 3. Fit the policy and test cancellation: The host stable-softplus calculation checks final margins.
for _ in range(120):
    value, g = step(theta)
    history.append(float(value))
    theta = theta - 0.4 * g

assert history[-1] < history[0] * 0.5
# Evaluate numerically stable log-space cross-entropy/likelihood (`policy`).
policy = jax.nn.log_softmax(theta)
# Convert `margin` to a host NumPy array for inspection or verification.
margin = np.asarray(
    (policy[chosen] - policy[rejected]) - (reference[chosen] - reference[rejected]),
    np.float64,
)
# Execute `np.testing.assert_allclose(`.
np.testing.assert_allclose(
    loss(theta), np.mean(np.logaddexp(0, -0.3 * margin)), atol=1e-6
)
assert np.all(margin > 0)
np.testing.assert_allclose(loss(theta + 50), loss(theta), atol=1e-6)
print(
    'DPO initial/final:',
    history[0],
    history[-1],
    '; reference-corrected margins:',
    margin,
)
```

The host stable-softplus calculation checks final margins. Adding a common logit offset preserves the probability distribution and therefore the objective.

## Run the example

```python
# Step 1 — 1. Define the reference-corrected pair objective: The reference correction is detached, while current policy log...
import jax
import jax.numpy as jnp
import numpy as np

# Define `dpo_loss(policy_logps, reference_logps, chosen, rejected...)` to evaluate the objective and its automatic derivatives:
def dpo_loss(policy_logps, reference_logps, chosen, rejected, beta=0.2):
    margin = (policy_logps[chosen] - policy_logps[rejected]) - jax.lax.stop_gradient(
        reference_logps[chosen] - reference_logps[rejected]
    )
    return jnp.mean(jax.nn.softplus(-beta * margin))

# Step 2 — 2. Freeze reference probabilities and comparison IDs: The initial policy equals a nonuniform reference.
reference = jax.nn.log_softmax(jnp.array([0.2, 0.0, -0.2]))
chosen = jnp.array([0, 0, 1])
rejected = jnp.array([1, 2, 2])
theta = jnp.array([0.2, 0.0, -0.2])
history = []
# Evaluate numerically stable log-space cross-entropy/likelihood (`loss`).
loss = lambda theta: dpo_loss(
    jax.nn.log_softmax(theta), reference, chosen, rejected, 0.3
)
# Differentiate the objective to obtain `step` via automatic differentiation.
step = jax.jit(jax.value_and_grad(loss))
np.testing.assert_allclose(loss(theta), np.log(2), atol=1e-6)

# Step 3 — 3. Fit the policy and test cancellation: The host stable-softplus calculation checks final margins.
for _ in range(120):
    value, g = step(theta)
    history.append(float(value))
    theta = theta - 0.4 * g

assert history[-1] < history[0] * 0.5
# Evaluate numerically stable log-space cross-entropy/likelihood (`policy`).
policy = jax.nn.log_softmax(theta)
# Convert `margin` to a host NumPy array for inspection or verification.
margin = np.asarray(
    (policy[chosen] - policy[rejected]) - (reference[chosen] - reference[rejected]),
    np.float64,
)
# Execute `np.testing.assert_allclose(`.
np.testing.assert_allclose(
    loss(theta), np.mean(np.logaddexp(0, -0.3 * margin)), atol=1e-6
)
assert np.all(margin > 0)
np.testing.assert_allclose(loss(theta + 50), loss(theta), atol=1e-6)
print(
    'DPO initial/final:',
    history[0],
    history[-1],
    '; reference-corrected margins:',
    margin,
)
```

Expected: Reference-corrected margins become positive and the initial equal-policy loss is log(2).

## Direct preference optimization and reference-corrected margins — recorded experiment

**Predict:** What does a positive corrected margin establish, and what does it leave unknown about absolute probabilities?

![Direct preference optimization and reference-corrected margins — recorded experiment](../figures/posttraining-05.svg)

**Recorded CPU computation**

### Read the figure

The line records preference loss before each update, starting at $0.693$ and falling to about $0.272$. It measures fit to the same three synthetic action comparisons. Its numerical scale depends on beta and does not directly compare with reward-model NLL or PPO reward.

The second panel shows final reference-corrected margins for each comparison. All positive bars mean those pairwise ratios improved relative to the reference. The zero-versus-two margin combines the other two gaps. A positive bar does not by itself prove the absolute probability of the chosen response increased; the separate three-action counterexample demonstrates why. Read these as log-ratio differences, not probabilities or human preference scores.

### Connect it to the computation

Positive final corrected margins mean the policy favors each chosen action more strongly relative to the reference. The independent host softplus calculation and reference-gradient check establish objective behavior; separate generation and human review would be needed for a language application.

```python
# Compute figure data for: Direct preference optimization and reference-corrected margins — recorded experiment
visual_data={'kind':'line','xlabel':'completed parameter updates before measurement','ylabel':'DPO preference loss (nats)','series':[{'label':'recorded CPU training loss','x':list(range(len(history))),'y':history}]}
for panel in visual_data.get('panels',[visual_data]):
    panel['x']=panel['series'][0]['x']

extra_panel={'kind':'bar','x':[0,1,2],'labels':['0 preferred to 1','0 preferred to 2','1 preferred to 2'],'series':[{'label':'final corrected margin','y':margin.tolist()}],'xlabel':'preference pair','ylabel':'reference-corrected log ratio','title':'Relative preference changes behind the loss'}
visual_data={"panels":[*visual_data.get("panels",[visual_data]),extra_panel]}
```

## Recorded reference execution

CPU run: 2026-10-20T10:52:21.092144+00:00. JAX 0.9.2.

```text
DPO initial/final: 0.6931471824645996 0.27227783203125 ; reference-corrected margins: [3.0890286  6.17805719 3.08902884]
Corrected/unadjusted initial loss: 0.6931471824645996 0.6540467739105225
Loss before/after: 0.6931471824645996 0.5418724417686462 ; chosen probability: 0.4 -> 0.3
Reversed-label loss: 1.5064733028411865
Reference gradient is zero.
One-pair logit gradient agrees with independent margin derivative.
PASS: posttraining-05

```

## Verify the reference cancellation

**Predict before running:** Can a nonuniform reference still start at log(2)?

```python
# Experiment — Verify the reference cancellation: The initial policy is not uniform.
initial = dpo_loss(reference, reference, chosen, rejected, 0.3)
np.testing.assert_allclose(initial, np.log(2), atol=1e-6)
# Aggregate array values to compute `uncorrected`.
uncorrected = jnp.mean(
    jax.nn.softplus(-0.3 * (reference[chosen] - reference[rejected]))
)
assert not np.isclose(float(initial), float(uncorrected))
print('Corrected/unadjusted initial loss:', float(initial), float(uncorrected))
```

**Expected:** The corrected initial loss is log(2); omitting the reference correction changes it.

The initial policy is not uniform. Cancellation, rather than equal response probabilities, makes the corrected margin zero.

## Improve the ratio while lowering the chosen probability

**Predict before running:** Can the preference loss fall even if the chosen response becomes less likely?

```python
# Experiment — Improve the ratio while lowering the chosen probability: The rejected probability falls further.
example_ref = jnp.log(jnp.array([0.4, 0.4, 0.2]))
example_policy = jnp.log(jnp.array([0.3, 0.1, 0.6]))
choice = jnp.array([0])
reject = jnp.array([1])
before = float(dpo_loss(example_ref, example_ref, choice, reject, 0.3))
after = float(dpo_loss(example_policy, example_ref, choice, reject, 0.3))
assert after < before and float(jnp.exp(example_policy[0])) < float(
    jnp.exp(example_ref[0])
)
np.testing.assert_allclose(after, np.logaddexp(0.0, -0.3 * np.log(3)), atol=1e-6)
print('Loss before/after:', before, after, '; chosen probability: 0.4 -> 0.3')
```

**Expected:** The DPO loss decreases while the chosen probability falls from 0.4 to 0.3.

The rejected probability falls further. Monitoring only the margin would miss the shift toward an unpaired response.

## Make it yours

Swap chosen and rejected IDs after training and verify that the loss rises.

### How to write this exercise — Step-by-step recipe & starter scaffold

**Key functions & syntax to use:**
- `dpo_loss(...)` — Call `dpo_loss` with your updated parameters or inputs from this lesson's workspace.
- `assert condition` — Verify that the observed output shape, status, or numerical value satisfies the contract.

**Step-by-step implementation plan:**
1. Set up the changed input or configuration parameters requested in the prompt.
2. Run the target function or transformation and assert that the output matches your prediction.

**Starter code scaffold (fill in the TODOs):**

```python
# Exercise solution: Swap chosen and rejected IDs after training and verify that the loss...
reverse = float(...)  # TODO: compute reverse
assert reverse  # TODO: complete assertion check
print('Reversed-label loss:', reverse)
```

<details><summary>Reference solution</summary>

```python
# Exercise solution: Swap chosen and rejected IDs after training and verify that the loss...
reverse = float(dpo_loss(policy, reference, rejected, chosen, 0.3))
assert reverse > float(dpo_loss(policy, reference, chosen, rejected, 0.3))
print('Reversed-label loss:', reverse)
```

</details>

## Freeze the reference numerically and in autodiff

**Transfer**

Differentiate with respect to reference log probabilities and verify that their gradient is zero.

<details><summary>Hint</summary>

The reference is an input to the objective but not an optimization variable.

</details>

### How to write: Freeze the reference numerically and in autodiff — Step-by-step recipe & starter scaffold

**Key functions & syntax to use:**
- `jax.grad(loss_fn)(params, ...)` — Transforms a scalar-output function into a function returning the gradient PyTree with the same structure as `params`.

**Step-by-step implementation plan:**
1. Differentiate the objective to obtain `reference_grad` via automatic differentiation.
2. Allocate initialized array `` with the specified shape and dtype.

**Starter code scaffold (fill in the TODOs):**

```python
# Freeze the reference numerically and in autodiff (Transfer): Also retain the actual reference checkpoint and tokenizer...
# Differentiate the objective to obtain `reference_grad` via automatic differentiation.
reference_grad = jax.grad(...)  # TODO: compute reference_grad
    policy, reference, chosen, rejected, 0.3
)
# Allocate initialized array `` with the specified shape and dtype.
np.testing.assert_array_equal(
    reference_grad, np.zeros(reference_grad.shape)
)
print('Reference gradient is zero.')
```

<details><summary>Reference solution and reasoning</summary>

```python
# Freeze the reference numerically and in autodiff (Transfer): Also retain the actual reference checkpoint and tokenizer...
# Differentiate the objective to obtain `reference_grad` via automatic differentiation.
reference_grad = jax.grad(dpo_loss, argnums=1)(
    policy, reference, chosen, rejected, 0.3
)
# Allocate initialized array `` with the specified shape and dtype.
np.testing.assert_array_equal(
    reference_grad, np.zeros(reference_grad.shape)
)
print('Reference gradient is zero.')
```

Also retain the actual reference checkpoint and tokenizer identity. A detached but reloaded different model is still a changed reference.

</details>

## Derive a one-pair categorical gradient

**Challenge**

At a fresh three-action policy, compute the corrected margin and derive the logit gradient for one chosen/rejected pair. Why does the third action have zero direct logit gradient here?

<details><summary>Hint</summary>

The log-softmax normalizer cancels in a log-probability difference. Shared model parameters make real sequence updates less isolated.

</details>

### How to write: Derive a one-pair categorical gradient — Step-by-step recipe & starter scaffold

**Key functions & syntax to use:**
- `jnp.array(values, dtype=...)` — Constructs an immutable device-backed JAX array from Python/NumPy values.
- `jnp.allclose(actual, expected, rtol=..., atol=...)` — Checks that two arrays match elementwise within floating-point tolerance.
- `jax.grad(loss_fn)(params, ...)` — Transforms a scalar-output function into a function returning the gradient PyTree with the same structure as `params`.

**Step-by-step implementation plan:**
1. Evaluate numerically stable log-space cross-entropy/likelihood (`one_pair`).
2. Differentiate the objective to obtain gradients ``.

**Starter code scaffold (fill in the TODOs):**

```python
# Derive a one-pair categorical gradient (Challenge): The unpaired logit is absent from this categorical...
probe = jnp.array(...)  # TODO: compute probe
choice = jnp.array(...)  # TODO: compute choice
reject = jnp.array(...)  # TODO: compute reject
beta = ...  # TODO: compute beta
# Evaluate numerically stable log-space cross-entropy/likelihood (`one_pair`).
one_pair = ...  # TODO: compute one_pair
    jax.nn.log_softmax(logits), reference, choice, reject, beta
)
margin_value = float(...)  # TODO: compute margin_value
factor = ...  # TODO: compute factor
# Differentiate the objective to obtain gradients ``.
np.testing.assert_allclose(
    jax.grad(one_pair)(probe), [factor, -factor, 0.0], atol=1e-6
)
print('One-pair logit gradient agrees with independent margin derivative.')
```

<details><summary>Reference solution and reasoning</summary>

```python
# Derive a one-pair categorical gradient (Challenge): The unpaired logit is absent from this categorical...
probe = jnp.array([0.6, -0.3, 0.1])
choice = jnp.array([0])
reject = jnp.array([1])
beta = 0.3
# Evaluate numerically stable log-space cross-entropy/likelihood (`one_pair`).
one_pair = lambda logits: dpo_loss(
    jax.nn.log_softmax(logits), reference, choice, reject, beta
)
margin_value = float((probe[0] - probe[1]) - (reference[0] - reference[1]))
factor = -beta / (1 + np.exp(beta * margin_value))
# Differentiate the objective to obtain gradients ``.
np.testing.assert_allclose(
    jax.grad(one_pair)(probe), [factor, -factor, 0.0], atol=1e-6
)
print('One-pair logit gradient agrees with independent margin derivative.')
```

The unpaired logit is absent from this categorical difference, yet its normalized probability can change when the other logits move.

</details>

## Check your understanding

Does this DPO loop require a separately trained reward model and fresh policy rollouts?

1. No. It optimizes reference-corrected preferences from the supplied pairs.
2. No, and a positive reference-corrected margin guarantees that the absolute chosen probability increased.
3. Yes, because the reference log-probability difference must be re-estimated from on-policy rollouts each step.

<details><summary>Answer and explanation</summary>

No. It optimizes reference-corrected preferences from the supplied pairs.

Its data and objective differ from the learned-reward PPO loop; evaluation quality remains a separate question.

</details>

## Diagnose the result

If initial loss is not log(2) when current equals reference, inspect the subtraction and masks. If reversed preferences still improve the reported score, inspect label direction and cached-reference alignment.

## Carry forward

- Subtract the frozen reference log-probability gap from the policy gap so the corrected margin is zero and the initial DPO loss equals $\log 2$ whenever $\pi_\theta = \pi_{\mathrm{ref}}$.
- Monitor chosen and rejected sequence log probabilities alongside the reference-corrected margin, because improving the relative ratio does not guarantee that absolute chosen probability increases.

## Keep your evidence

Keep reference identity, response log-probability conventions, log(2) initialization, independent margin loss, reversed labels and frozen-reference checks.

Save your predictions, modified code, terminal outputs, and reasoning in your engineering portfolio.

## Primary references

- [Direct Preference Optimization](https://arxiv.org/abs/2305.18290)

