 JAX Pathways
Phase 18 / Post-training: SFT, LoRA, reward models and RLHF
RLHF mechanics: a frozen reward and PPO policy updates
Revision v0.7.0 · Updated since your last visit. Review the changes; your progress is saved.
Lesson · about 105 minutes · CPU practice
Keep three identities separate. Collect actions before optimizing them.
Phase study guide: preparation, milestones and project evidence
Before you start
Before this: Learn a reward model from pairwise preferences
Hardware: CPU
Setup help: Python, notebook, or Cloud TPU VM
Use the tested CPU packages (the recorded environment uses Python 3.14.3). Other Python versions and accelerator environments require separate checks. The optional Cloud TPU specialization explains the target-specific execution boundaries. Logical CPU devices practice partitioning; they do not simulate TPU performance.
Download the repository ZIP or use your existing checkout. Extract it and open a terminal in the folder containing requirements-cpu.txt. The beginner ZIP is separate; these lessons use the full repository folder.
python3 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements-cpu.txtpy -3 -m venv .venv
.\.venv\Scripts\python.exe -m pip install -r requirements-cpu.txtAfter activation, run the complete worked example from that same folder:
python phases/18-posttraining/04-rlhf/code/main.py.\.venv\Scripts\python.exe phases/18-posttraining/04-rlhf/code/main.pyFor an incremental build, create main.py in your own practice folder, append each build block in order, and run python main.py with this environment active. Keep that file separate from the downloaded reference solution.
Download this lesson’s notebook. Open it with a Python kernel using the course environment. Run cells from the top after restarting the kernel; experiments depend on earlier definitions.
For local Jupyter, first install the course requirements using the Local Python steps, then use your environment’s Python to start Jupyter:
python -m pip install jupyterlab
python -m jupyter lab.\.venv\Scripts\python.exe -m pip install jupyterlab
.\.venv\Scripts\python.exe -m jupyter labSelect the downloaded posttraining-04.ipynb file in JupyterLab. The notebook contains reference solutions; make your prediction and attempt each practice task before opening them. Restart the kernel before changing logical device setup.
The worked reference for this lesson is CPU-validated. Some references explicitly configure logical CPU devices; setting JAX_PLATFORMS does not adapt them to a TPU. Follow the execution matrix and reviewed multi-host example before attempting a target run.
For accelerator preparation, study TPU setup, observed runtime receipts, checkpointed jobs and precision and retained traces. These target paths remain unqualified on physical TPU hardware until an actual receipt is recorded. Cloud provisioning is optional for CPU learning.
Check: Sampled PPO updates increase exact expected learned reward while the reference stays unchanged.
Revisit the guided CPU setup · Open 19: TPU Setup. Package instructions are CPU instructions; Windows and accelerator environments need their own validation.
What you will be able to do
- Keep three identities separate
- Collect actions before optimizing them
- Verify the changed-condition exercise and explain the limits of this fixture.
The problem
After fitting a reward model, how do its scores change a policy? We will collect actual sampled actions, freeze the behavior probabilities for each rollout batch and inspect improvement together with drift from a fixed reference.
The idea
This lesson isolates RLHF mechanics in a small categorical bandit. A trainable policy is compared with rollout-time probabilities and a fixed reference, while a previously fitted reward model supplies frozen scores. Each role has a different update lifetime.
Keep the four policy-and-reward roles distinct
Before this lesson, complete rl-01 through rl-04: functional environments, rollout masks, behavior-policy identity, signed PPO clipping and held-out evaluation. This is an additional prerequisite for learned-reward policy optimization, not for response-only SFT or LoRA.
The old policy probabilities stay fixed during the inner PPO updates for one rollout batch. They refresh when a new rollout is collected. The reference policy remains fixed across those rollouts and defines the KL comparison. The reward model is frozen during policy optimization.
Advantages and old probabilities should not quietly become new optimization targets during the inner update. This fixture uses an exact baseline and categorical KL; it does not contain a learned language-model critic or human-feedback collection pipeline.
Read reward, KL and action-probability panels together. Higher reward accompanied by a larger reference deviation is a tradeoff, not an unqualified success. Keep each plotted quantity tied to the actual policy state at measurement.
Different objects have different update lifetimes
Predict: Which frozen object refreshes between rollout batches: old policy probabilities or the reference policy?
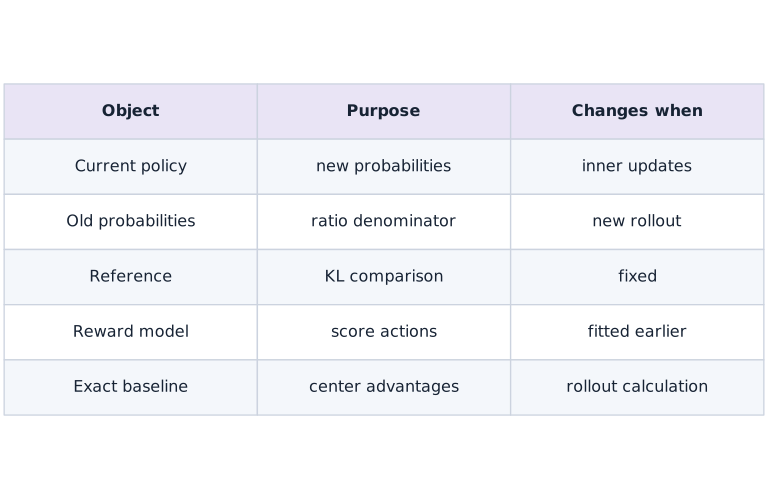
Current parameters change within PPO updates. Old probabilities stay fixed for that rollout batch and refresh next rollout. The reference and reward remain fixed during policy training. This categorical fixture has an exact baseline, so no learned critic is shown.
Before coding: identify four different objects
Keep a notebook table with current policy, old behavior policy, reference policy and reward model. The current policy changes on optimizer steps. The old policy is a snapshot taken before collecting the batch; its sampled-action log probabilities stay fixed while reusing that batch. The reference and reward model stay fixed for the whole experiment. Confusing old and reference makes even a numerically stable loop implement the wrong objective.
This lab is a bandit: one prompt, three terminal actions and no sequence credit assignment. It lets us calculate expectations exactly. Language PPO additionally needs token masks, rollout termination, value/advantage estimation and a generation pipeline; none of those can be inferred from this loop.
Keep three identities separate
The reward model scores outputs. The reference policy anchors the desired deviation penalty and stays fixed. The old behavior policy generated the current batch and remains fixed only while that batch is reused. At the next rollout, old behavior updates to the new policy; the reference does not.
Collect actions before optimizing them
The code samples terminal response actions from the current categorical policy. It stores their old log probabilities and computes an advantage using the frozen reward minus that policy’s exact expected reward. This exact baseline is available only because the action space is tiny; a general language system needs a suitable baseline or value estimator.
Work a signed clipping example
For advantage , ratio , and clip interval , the products are and , so the minimum is . Further increasing this ratio no longer improves that positive-advantage surrogate term. For and , the products are and , so the minimum is .
Clipping limits the reward for moving in the advantageous direction too far on these samples. It does not freeze all probability changes or prove a global trust region. The explicit KL term can still contribute gradients when a surrogate term is clipped. Read the negative sign in the minimized loss carefully: we minimize negative surrogate plus a penalty.
Why a baseline can help without changing the expected gradient
For sampled action , the advantage here is reward minus the old policy’s exact expected reward. The baseline is independent of which action was sampled and is frozen for the update. Its expected contribution to the unclipped score-function gradient is zero because policy probabilities sum to one. Subtracting it can reduce sampling variance without changing that expected gradient.
Our three-action environment lets you enumerate this identity instead of trusting a noisy Monte Carlo comparison. The identity alone does not prove that arbitrary baselines, clipped multi-epoch surrogates or learned value estimators are unbiased. Preserve which estimator is being checked.
Clip the surrogate with the advantage sign intact
Form a probability ratio from current and old log probabilities. Take the minimum of unclipped and clipped advantage products. Negative advantages reverse which bound matters; clipping only the ratio and maximizing it indiscriminately changes the algorithm. Advantages and behavior probabilities are detached.
Measure reward and reference drift together
For this categorical bandit, compute the KL and expected learned reward exactly by summing over every action. The trainer includes this exact KL directly in the objective; it is not an implementation of every token-level reward-shaping variant. A higher reward with greater KL may be expected, and clipping does not guarantee a global trust region.
Do not confuse reward optimization with alignment
The model can exploit a weak reward model. Keep independent evaluations, inspect unfavorable cases and fix reward/reference versions during a comparison. Actual human-feedback systems need human data provenance and held-out human judgments. This exercise demonstrates sampled policy optimization against a learned synthetic preference reward only.
Use the exact solution as a bounded optimization reference
For a finite action space with positive reference probabilities, maximizing expected fixed reward minus times forward KL has optimum proportional to reference probability times . This is a reference for the regularized bandit problem, not a statement that forty sampled PPO iterations must reach it. Compute it with log-softmax for numerical stability.
Evaluate the regularized objective of your trained policy and this optimum. A gap can reflect finite optimization, clipping and sampled rollouts. A higher learned reward alone can come from excessive drift. Keep an independent task score and adversarial cases before carrying this pattern to a real reward model.
RLHF mechanics: a frozen reward and PPO policy updates — recorded experiment
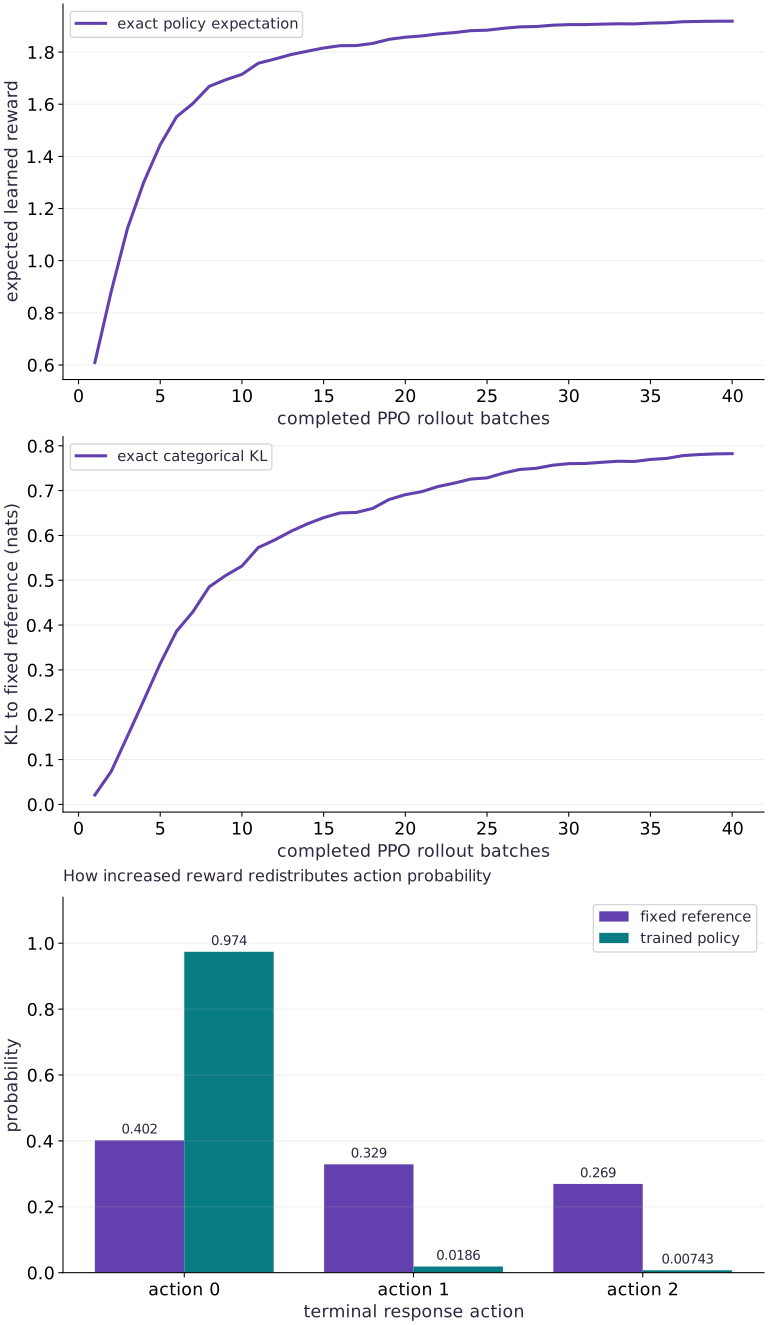
Predict before looking: Which action gains probability as reward rises, and why does that also change reference KL?
Read the figure
The top panel shows exact expected learned reward after each rollout batch, rising toward the highest-scored action. The bottom panel shows exact KL in nats to the fixed reference. The final reward is about , with KL about . The axes are different quantities and must not be added as if they shared units.
The third panel compares reference and final action probabilities; each series sums to one. Probability moves toward action zero, the response favored by the learned reward. The other actions lose probability, explaining the rising expected reward and KL in the first two panels. Reward is measured in the learned score scale, KL in nats and these bars in probability: do not combine their heights. This is a finite synthetic policy distribution, not a measure of human approval.
Connect it to the computation
The policy concentrates on the action favored by the learned reward, which also moves it away from the reference. These deterministic expectation measurements evaluate a policy trained from random rollouts; they are not sampled human preference scores or a safety assessment.
Open full-size figureDownload data and provenance
The notebook contains the data experiment, plotting code, and recorded figure output. Rerun it to test your changes.
Where to put & run this code: Work in phases/18-posttraining/04-rlhf/code/main.py (or downloaded exercises/posttraining-04.py / exercises/posttraining-04.ipynb) and execute from the repository root with python3 phases/18-posttraining/04-rlhf/code/main.py.
1 Define the reward likelihood and signed PPO loss
Create main.py in your activated course environment. Paste this block, then run python main.py; function definitions alone print nothing.
# Step 1 — 1. Define the reward likelihood and signed PPO loss: Keep reward fitting and policy loss separate.
import jax
import jax.numpy as jnp
import numpy as np

def preference_loss(w, chosen, rejected):
    # Perform matrix / vector contraction (`@`) to compute `margin`.
    margin = (chosen - rejected) @ w
    return jnp.mean(jax.nn.softplus(-margin))

# Define `ppo_loss(logits, old_logps, actions, advantages...)` to evaluate the objective and its automatic derivatives:
def ppo_loss(
    logits, old_logps, actions, advantages, reference_logps, beta=0.1, clip=0.2
):
    # Evaluate numerically stable log-space cross-entropy/likelihood (`logp`).
    logp = jax.nn.log_softmax(logits)
    ratios = jnp.exp(logp[actions] - jax.lax.stop_gradient(old_logps))
    advantages = jax.lax.stop_gradient(advantages)
    # Combine or mask array elements to form `clipped`.
    clipped = jnp.clip(ratios, 1.0 - clip, 1.0 + clip)
    surrogate = jnp.mean(jnp.minimum(ratios * advantages, clipped * advantages))
    # Exact categorical KL in this one-prompt, one-action teaching environment.
    kl = jnp.sum(
        jnp.exp(logp) * (logp - jax.lax.stop_gradient(reference_logps))
    )
    return -surrogate + beta * kl
Code building blocks in this step
x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).
Keep reward fitting and policy loss separate. Inside policy loss, old probabilities and advantages are constants for differentiation.
2 Fit and freeze reward, then identify reference state
Append this block to main.py and run python main.py again. Keep the earlier blocks above it.
# Step 2 — 2. Fit and freeze reward, then identify reference state: The reference is stored before policy updates.
features = jnp.array([[1.0, 0.0], [0.0, 1.0], [-1.0, -1.0]])
chosen = features[jnp.array([0, 0, 1])]
rejected = features[jnp.array([1, 2, 2])]
reward_w = jnp.zeros(2)
# Differentiate the objective to obtain `reward_step` via automatic differentiation.
reward_step = jax.jit(jax.grad(lambda w: preference_loss(w, chosen, rejected)))
for _ in range(100):
    reward_w = reward_w - 0.1 * reward_step(reward_w)
rewards = jax.lax.stop_gradient(features @ reward_w)
# A fixed reference policy and a learned reward, with one terminal response action.
reference = jax.nn.log_softmax(jnp.array([0.2, 0.0, -0.2]))
theta = jnp.array([0.2, 0.0, -0.2])
# Convert `reference_copy` to a host NumPy array for inspection or verification.
reference_copy = np.asarray(reference).copy()
# Create or split explicit PRNG key(s) (`key`) for reproducible randomness.
key = jax.random.key(11)
history = []
kl_history = []
# Evaluate both scalar loss and parameter gradients in one pass (`step`).
step = jax.jit(jax.value_and_grad(ppo_loss))
Code building blocks in this step
jnp.array(values, dtype=...)— Constructs an immutable device-backed JAX array from Python/NumPy values.jnp.zeros / jnp.ones(shape, dtype=...)— Allocates a tensor of the givenshapeinitialized with constants.jax.grad(loss_fn)(params, ...)— Transforms a scalar-output function into a function returning the gradient PyTree with the same structure asparams.jax.value_and_grad(loss_fn)(params, ...)— Evaluates both the scalar loss and its gradient PyTree(loss_val, grads)in a single forward+backward pass.
The reference is stored before policy updates. This step also creates the sampling key and independent reward model.
3 Collect rollouts and reuse each batch correctly
Append this block to main.py and run python main.py again. Keep the earlier blocks above it.
# Step 3 — 3. Collect rollouts and reuse each batch correctly: Each outer iteration collects a fresh batch; each inner step...
for iteration in range(40):
    # Evaluate numerically stable log-space cross-entropy/likelihood (`old`).
    old = jax.nn.log_softmax(theta)
    probs = jnp.exp(old)
    # Create or split explicit PRNG key(s) (`(key, draw)`) for reproducible randomness.
    key, draw = jax.random.split(key)
    # Draw pseudorandom samples for `actions` using the explicit RNG state.
    actions = jax.random.categorical(draw, old, shape=(128,))
    old_selected = jax.lax.stop_gradient(old[actions])
    advantage = jax.lax.stop_gradient(
        rewards[actions] - jnp.sum(probs * rewards)
    )
    for _ in range(3):
        _, g = step(
            theta, old_selected, actions, advantage, reference, 0.2, 0.2
        )
        theta = theta - 0.15 * g
    # Evaluate numerically stable log-space cross-entropy/likelihood (`logp`).
    logp = jax.nn.log_softmax(theta)
    history.append(float(jnp.sum(jnp.exp(logp) * rewards)))
    kl_history.append(float(jnp.sum(jnp.exp(logp) * (logp - reference))))

# Execute `np.testing.assert_array_equal(reference, reference_copy)`
np.testing.assert_array_equal(reference, reference_copy)
# Aggregate array values to compute `initial_reward`.
initial_reward = float(jnp.sum(jnp.exp(reference) * rewards))
assert history[-1] > initial_reward and kl_history[-1] > 0
# Independent finite-action expectation: no evaluation sampling error here.
np.testing.assert_allclose(
    history[-1],
    sum(float(a) * float(b) for a, b in zip(jnp.exp(logp), rewards)),
    rtol=1e-6,
)
print(
    'Reward initial/final and final KL:',
    initial_reward,
    history[-1],
    kl_history[-1],
)
print(
    'Synthetic preference bandit with actual sampled PPO updates; synthetic preference target or language-generation claim.'
)
Code building blocks in this step
x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.jax.random.PRNGKey(seed) & jax.random.split(key)— Manages explicit, stateless PRNG keys—always split a key before passing subkeys into independent random draws.
Each outer iteration collects a fresh batch; each inner step reuses its saved behavior probabilities. Plot points occur after a rollout batch, unlike pre-update loss curves in other lessons.
View the cumulative build in main.py
These blocks append in order to the same file.
# Step 1 — 1. Define the reward likelihood and signed PPO loss: Keep reward fitting and policy loss separate.
import jax
import jax.numpy as jnp
import numpy as np

def preference_loss(w, chosen, rejected):
    # Perform matrix / vector contraction (`@`) to compute `margin`.
    margin = (chosen - rejected) @ w
    return jnp.mean(jax.nn.softplus(-margin))

# Define `ppo_loss(logits, old_logps, actions, advantages...)` to evaluate the objective and its automatic derivatives:
def ppo_loss(
    logits, old_logps, actions, advantages, reference_logps, beta=0.1, clip=0.2
):
    # Evaluate numerically stable log-space cross-entropy/likelihood (`logp`).
    logp = jax.nn.log_softmax(logits)
    ratios = jnp.exp(logp[actions] - jax.lax.stop_gradient(old_logps))
    advantages = jax.lax.stop_gradient(advantages)
    # Combine or mask array elements to form `clipped`.
    clipped = jnp.clip(ratios, 1.0 - clip, 1.0 + clip)
    surrogate = jnp.mean(jnp.minimum(ratios * advantages, clipped * advantages))
    # Exact categorical KL in this one-prompt, one-action teaching environment.
    kl = jnp.sum(
        jnp.exp(logp) * (logp - jax.lax.stop_gradient(reference_logps))
    )
    return -surrogate + beta * kl

# Step 2 — 2. Fit and freeze reward, then identify reference state: The reference is stored before policy updates.
features = jnp.array([[1.0, 0.0], [0.0, 1.0], [-1.0, -1.0]])
chosen = features[jnp.array([0, 0, 1])]
rejected = features[jnp.array([1, 2, 2])]
reward_w = jnp.zeros(2)
# Differentiate the objective to obtain `reward_step` via automatic differentiation.
reward_step = jax.jit(jax.grad(lambda w: preference_loss(w, chosen, rejected)))
for _ in range(100):
    reward_w = reward_w - 0.1 * reward_step(reward_w)
rewards = jax.lax.stop_gradient(features @ reward_w)
# A fixed reference policy and a learned reward, with one terminal response action.
reference = jax.nn.log_softmax(jnp.array([0.2, 0.0, -0.2]))
theta = jnp.array([0.2, 0.0, -0.2])
# Convert `reference_copy` to a host NumPy array for inspection or verification.
reference_copy = np.asarray(reference).copy()
# Create or split explicit PRNG key(s) (`key`) for reproducible randomness.
key = jax.random.key(11)
history = []
kl_history = []
# Evaluate both scalar loss and parameter gradients in one pass (`step`).
step = jax.jit(jax.value_and_grad(ppo_loss))

# Step 3 — 3. Collect rollouts and reuse each batch correctly: Each outer iteration collects a fresh batch; each inner step...
for iteration in range(40):
    # Evaluate numerically stable log-space cross-entropy/likelihood (`old`).
    old = jax.nn.log_softmax(theta)
    probs = jnp.exp(old)
    # Create or split explicit PRNG key(s) (`(key, draw)`) for reproducible randomness.
    key, draw = jax.random.split(key)
    # Draw pseudorandom samples for `actions` using the explicit RNG state.
    actions = jax.random.categorical(draw, old, shape=(128,))
    old_selected = jax.lax.stop_gradient(old[actions])
    advantage = jax.lax.stop_gradient(
        rewards[actions] - jnp.sum(probs * rewards)
    )
    for _ in range(3):
        _, g = step(
            theta, old_selected, actions, advantage, reference, 0.2, 0.2
        )
        theta = theta - 0.15 * g
    # Evaluate numerically stable log-space cross-entropy/likelihood (`logp`).
    logp = jax.nn.log_softmax(theta)
    history.append(float(jnp.sum(jnp.exp(logp) * rewards)))
    kl_history.append(float(jnp.sum(jnp.exp(logp) * (logp - reference))))

# Execute `np.testing.assert_array_equal(reference, reference_copy)`
np.testing.assert_array_equal(reference, reference_copy)
# Aggregate array values to compute `initial_reward`.
initial_reward = float(jnp.sum(jnp.exp(reference) * rewards))
assert history[-1] > initial_reward and kl_history[-1] > 0
# Independent finite-action expectation: no evaluation sampling error here.
np.testing.assert_allclose(
    history[-1],
    sum(float(a) * float(b) for a, b in zip(jnp.exp(logp), rewards)),
    rtol=1e-6,
)
print(
    'Reward initial/final and final KL:',
    initial_reward,
    history[-1],
    kl_history[-1],
)
print(
    'Synthetic preference bandit with actual sampled PPO updates; synthetic preference target or language-generation claim.'
)
Run the example
python3 phases/18-posttraining/04-rlhf/code/main.pyAbout this command
This shortcut uses an activated macOS/Linux course environment in the repository folder. For Windows, use the explicit interpreter command in “Setup help” above. The script includes worked examples and reference solutions.
Inspect the complete assembled example
# Step 1 — 1. Define the reward likelihood and signed PPO loss: Keep reward fitting and policy loss separate.
import jax
import jax.numpy as jnp
import numpy as np

def preference_loss(w, chosen, rejected):
    # Perform matrix / vector contraction (`@`) to compute `margin`.
    margin = (chosen - rejected) @ w
    return jnp.mean(jax.nn.softplus(-margin))

# Define `ppo_loss(logits, old_logps, actions, advantages...)` to evaluate the objective and its automatic derivatives:
def ppo_loss(
    logits, old_logps, actions, advantages, reference_logps, beta=0.1, clip=0.2
):
    # Evaluate numerically stable log-space cross-entropy/likelihood (`logp`).
    logp = jax.nn.log_softmax(logits)
    ratios = jnp.exp(logp[actions] - jax.lax.stop_gradient(old_logps))
    advantages = jax.lax.stop_gradient(advantages)
    # Combine or mask array elements to form `clipped`.
    clipped = jnp.clip(ratios, 1.0 - clip, 1.0 + clip)
    surrogate = jnp.mean(jnp.minimum(ratios * advantages, clipped * advantages))
    # Exact categorical KL in this one-prompt, one-action teaching environment.
    kl = jnp.sum(
        jnp.exp(logp) * (logp - jax.lax.stop_gradient(reference_logps))
    )
    return -surrogate + beta * kl

# Step 2 — 2. Fit and freeze reward, then identify reference state: The reference is stored before policy updates.
features = jnp.array([[1.0, 0.0], [0.0, 1.0], [-1.0, -1.0]])
chosen = features[jnp.array([0, 0, 1])]
rejected = features[jnp.array([1, 2, 2])]
reward_w = jnp.zeros(2)
# Differentiate the objective to obtain `reward_step` via automatic differentiation.
reward_step = jax.jit(jax.grad(lambda w: preference_loss(w, chosen, rejected)))
for _ in range(100):
    reward_w = reward_w - 0.1 * reward_step(reward_w)
rewards = jax.lax.stop_gradient(features @ reward_w)
# A fixed reference policy and a learned reward, with one terminal response action.
reference = jax.nn.log_softmax(jnp.array([0.2, 0.0, -0.2]))
theta = jnp.array([0.2, 0.0, -0.2])
# Convert `reference_copy` to a host NumPy array for inspection or verification.
reference_copy = np.asarray(reference).copy()
# Create or split explicit PRNG key(s) (`key`) for reproducible randomness.
key = jax.random.key(11)
history = []
kl_history = []
# Evaluate both scalar loss and parameter gradients in one pass (`step`).
step = jax.jit(jax.value_and_grad(ppo_loss))

# Step 3 — 3. Collect rollouts and reuse each batch correctly: Each outer iteration collects a fresh batch; each inner step...
for iteration in range(40):
    # Evaluate numerically stable log-space cross-entropy/likelihood (`old`).
    old = jax.nn.log_softmax(theta)
    probs = jnp.exp(old)
    # Create or split explicit PRNG key(s) (`(key, draw)`) for reproducible randomness.
    key, draw = jax.random.split(key)
    # Draw pseudorandom samples for `actions` using the explicit RNG state.
    actions = jax.random.categorical(draw, old, shape=(128,))
    old_selected = jax.lax.stop_gradient(old[actions])
    advantage = jax.lax.stop_gradient(
        rewards[actions] - jnp.sum(probs * rewards)
    )
    for _ in range(3):
        _, g = step(
            theta, old_selected, actions, advantage, reference, 0.2, 0.2
        )
        theta = theta - 0.15 * g
    # Evaluate numerically stable log-space cross-entropy/likelihood (`logp`).
    logp = jax.nn.log_softmax(theta)
    history.append(float(jnp.sum(jnp.exp(logp) * rewards)))
    kl_history.append(float(jnp.sum(jnp.exp(logp) * (logp - reference))))

# Execute `np.testing.assert_array_equal(reference, reference_copy)`
np.testing.assert_array_equal(reference, reference_copy)
# Aggregate array values to compute `initial_reward`.
initial_reward = float(jnp.sum(jnp.exp(reference) * rewards))
assert history[-1] > initial_reward and kl_history[-1] > 0
# Independent finite-action expectation: no evaluation sampling error here.
np.testing.assert_allclose(
    history[-1],
    sum(float(a) * float(b) for a, b in zip(jnp.exp(logp), rewards)),
    rtol=1e-6,
)
print(
    'Reward initial/final and final KL:',
    initial_reward,
    history[-1],
    kl_history[-1],
)
print(
    'Synthetic preference bandit with actual sampled PPO updates; synthetic preference target or language-generation claim.'
)
Expected result: Sampled PPO updates increase exact expected learned reward while the reference stays unchanged.
Recorded reference execution
Reference output captured from executing the complete lesson script (code/main.py) and its assertions in the course CPU environment.
Reward initial/final and final KL: 0.28191882371902466 1.9185447692871094 0.7824773192405701
Synthetic preference bandit with actual sampled PPO updates; synthetic preference target or language-generation claim.
Reward initial/final and final KL: 0.28191882371902466 1.9185447692871094 0.7824773192405701
Synthetic preference bandit with actual sampled PPO updates; synthetic preference target or language-generation claim.
Clipped surrogate terms: [ 2.4 -1.6]
Enumerated baseline score gradient matches exact expected-reward gradient.
Reference/final KL: 0.0 0.7824773192405701
Behavior log probabilities and advantages are detached.
Regularized objective reference/trained/optimum: 0.28191882371902466 1.7620493173599243 1.7987911701202393
PASS: posttraining-04
Download execution record · The notebook includes executed cells and figure outputs. Compare your run with these values; timings depend on the machine.
Inspect both clipping directions
# Experiment — Inspect both clipping directions: The negative-advantage case selects the more negative product.
ratios = np.array([1.5, 0.5])
advantages = np.array([2.0, -2.0])
terms = np.minimum(
    ratios * advantages, np.clip(ratios, 0.8, 1.2) * advantages
)
# Execute `np.testing.assert_allclose(terms, [2.4, -1.6])`
np.testing.assert_allclose(terms, [2.4, -1.6])
print('Clipped surrogate terms:', terms)
Expected: The terms are [2.4, -1.6].
The negative-advantage case selects the more negative product. This is why clipping must be applied inside the signed surrogate.
Enumerate the baseline cancellation
# Experiment — Enumerate the baseline cancellation: Enumeration removes sampling error.
probe = jnp.array([0.3, -0.2, 0.1])
# Apply nonlinear activation or probability normalization to compute `probe_probs`.
probe_probs = jax.nn.softmax(probe)
# Aggregate array values to compute `constant`.
constant = float(jnp.sum(probe_probs * rewards))
# Compute exact directional derivative / Jacobian / Hessian (`score_jacobian`).
score_jacobian = jax.jacrev(jax.nn.log_softmax)(probe)
# Reduce along axis=0 to compute `enumerated`.
enumerated = jnp.sum(
    probe_probs[:, None] * (rewards - constant)[:, None] * score_jacobian,
    axis=0,
)
# Differentiate the objective to obtain `exact` via automatic differentiation.
exact = jax.grad(lambda logits: jnp.sum(jax.nn.softmax(logits) * rewards))(
    probe
)
np.testing.assert_allclose(enumerated, exact, atol=1e-6)
print('Enumerated baseline score gradient matches exact expected-reward gradient.')
Expected: The two gradients agree up to float32 rounding.
Enumeration removes sampling error. This tests the unclipped estimator identity; it does not assert that every clipped update equals exact gradient ascent.
Make it yours
Where to put your code: Append your solution at the bottom of phases/18-posttraining/04-rlhf/code/main.py (or inside the Make it yours cell of exercises/posttraining-04.ipynb) and run python3 phases/18-posttraining/04-rlhf/code/main.py to verify your prediction before opening the reference solution.
Check the KL at the fixed reference and compare it with the final policy’s exact KL.
Show a writing guide and starter scaffold
How to write this exercise code: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).
2. Step-by-step implementation plan:
- Aggregate array values to compute
zero_kl.
# Exercise solution: Check the KL at the fixed reference and compare it with the final...
# Aggregate array values to compute `zero_kl`.
zero_kl = float(...)  # TODO: compute zero_kl
assert zero_kl  # TODO: complete assertion check
print('Reference/final KL:', zero_kl, kl_history[-1])
Reveal the reference solution
# Exercise solution: Check the KL at the fixed reference and compare it with the final...
# Aggregate array values to compute `zero_kl`.
zero_kl = float(jnp.sum(jnp.exp(reference) * (reference - reference)))
assert zero_kl == 0.0 and kl_history[-1] > zero_kl
print('Reference/final KL:', zero_kl, kl_history[-1])
Verify detached behavior information
Transfer
Differentiate the objective with respect to supplied old log probabilities and advantages; both must be fixed within this update.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
jax.grad(loss_fn)(params, ...)— Transforms a scalar-output function into a function returning the gradient PyTree with the same structure asparams.
2. Step-by-step implementation plan:
- Differentiate the objective to obtain
(old_grad, adv_grad)via automatic differentiation. - Allocate initialized array
with the specified shape and dtype. - Allocate initialized array
with the specified shape and dtype.
# Verify detached behavior information (Transfer): Detaching is not enough if you recompute old probabilities...
# Differentiate the objective to obtain `(old_grad, adv_grad)` via automatic differentiation.
old_grad, adv_grad = jax.grad(...)  # TODO: compute old_grad, adv_grad
    theta, old_selected, actions, advantage, reference, 0.2, 0.2
)
# Allocate initialized array `` with the specified shape and dtype.
np.testing.assert_array_equal(old_grad, np.zeros(old_grad.shape))
# Allocate initialized array `` with the specified shape and dtype.
np.testing.assert_array_equal(adv_grad, np.zeros(adv_grad.shape))
print('Behavior log probabilities and advantages are detached.')
Show a hint
Use argnums to inspect only those two inputs.
Reveal reference solution and reasoning
# Verify detached behavior information (Transfer): Detaching is not enough if you recompute old probabilities...
# Differentiate the objective to obtain `(old_grad, adv_grad)` via automatic differentiation.
old_grad, adv_grad = jax.grad(ppo_loss, argnums=(1, 3))(
    theta, old_selected, actions, advantage, reference, 0.2, 0.2
)
# Allocate initialized array `` with the specified shape and dtype.
np.testing.assert_array_equal(old_grad, np.zeros(old_grad.shape))
# Allocate initialized array `` with the specified shape and dtype.
np.testing.assert_array_equal(adv_grad, np.zeros(adv_grad.shape))
print('Behavior log probabilities and advantages are detached.')
Detaching is not enough if you recompute old probabilities after every optimizer step. Store their values at collection time and verify identity across all epochs on that batch.
Compare with the finite-action regularized optimum
Challenge
Compute the analytic optimum for beta 0.2, then compare its regularized objective with the trained policy and the reference.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).
2. Step-by-step implementation plan:
- Evaluate numerically stable log-space cross-entropy/likelihood (
optimal_logp).
# Compare with the finite-action regularized optimum (Challenge): An independently derived optimum bounds this finite-action...
beta = ...  # TODO: compute beta
# Evaluate numerically stable log-space cross-entropy/likelihood (`optimal_logp`).
optimal_logp = jax.nn.log_softmax(...)  # TODO: compute optimal_logp

def regularized(logp):
    return ...  # TODO: return computed result
        jnp.exp(logp) * (logp - reference)
    )

optimum = float(...)  # TODO: compute optimum
trained = float(...)  # TODO: compute trained
baseline = float(...)  # TODO: compute baseline
assert optimum  # TODO: complete assertion check
print(
    'Regularized objective reference/trained/optimum:',
    baseline,
    trained,
    optimum,
)
Show a hint
Evaluate expected reward minus beta times KL for all three policies, and compute the optimum in log space.
Reveal reference solution and reasoning
# Compare with the finite-action regularized optimum (Challenge): An independently derived optimum bounds this finite-action...
beta = 0.2
# Evaluate numerically stable log-space cross-entropy/likelihood (`optimal_logp`).
optimal_logp = jax.nn.log_softmax(reference + rewards / beta)

def regularized(logp):
    return jnp.sum(jnp.exp(logp) * rewards) - beta * jnp.sum(
        jnp.exp(logp) * (logp - reference)
    )

optimum = float(regularized(optimal_logp))
trained = float(regularized(logp))
baseline = float(regularized(reference))
assert optimum >= trained - 1e-5 and optimum >= baseline - 1e-5
print(
    'Regularized objective reference/trained/optimum:',
    baseline,
    trained,
    optimum,
)
An independently derived optimum bounds this finite-action objective. It does not qualify language generation or the reward model’s judgment.
Diagnose the result
If ratios always equal one during repeated updates, inspect whether old log probabilities are being recomputed. If reward grows while external quality falls, investigate reward exploitation instead of declaring alignment.
Carry forward
- Keep four update lifetimes distinct: the current policy updates each inner PPO step, behavior log probabilities and advantages stay fixed across epochs on a rollout batch, and the reference policy and reward model stay frozen across the run.
- Apply ratio clipping inside the signed product and track expected reward alongside reference KL .
Keep your evidence
Keep reward/reference identity, collected old probabilities, signed clipping checks, exact reward/KL history and detached behavior information.
Save your modified code, its output, and an explanation of your prediction. Checkpoint answers and exercise evidence are tracked separately.
Saved in this browser. Export or back up your portfolio anytime in My learning.
Verified on local CPU. Stage to a Cloud TPU VM via Cloud TPU setup to record accelerator execution receipts (TODO: add automated Cloud TPU CI execution receipts).