 JAX Pathways
Phase 00 / Setup & first steps
Practice with four virtual CPU devices
Revision v0.7.0 · Updated since your last visit. Review the changes; your progress is saved.
Lesson · about 60 minutes · Logical CPU devices
Start four logical CPU devices, inspect row-sharded and replicated arrays, and diagnose an indivisible batch.
Phase study guide: preparation, milestones and project evidence
Before you start
Before this: Meet your arrays and devices
Hardware: 4 logical CPU devices on one host
Setup help: Python, notebook, or Cloud TPU VM
Use the tested CPU packages (the recorded environment uses Python 3.14.3). Other Python versions and accelerator environments require separate checks. The optional Cloud TPU specialization explains the target-specific execution boundaries. Logical CPU devices practice partitioning; they do not simulate TPU performance.
Download the repository ZIP or use your existing checkout. Extract it and open a terminal in the folder containing requirements-cpu.txt. The beginner ZIP is separate; these lessons use the full repository folder.
python3 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements-cpu.txtpy -3 -m venv .venv
.\.venv\Scripts\python.exe -m pip install -r requirements-cpu.txtAfter activation, run the complete worked example from that same folder:
python phases/00-welcome/03-virtual-cpu-devices/code/main.py.\.venv\Scripts\python.exe phases/00-welcome/03-virtual-cpu-devices/code/main.pyFor an incremental build, create main.py in your own practice folder, append each build block in order, and run python main.py with this environment active. Keep that file separate from the downloaded reference solution.
Download this lesson’s notebook. Open it with a Python kernel using the course environment. Run cells from the top after restarting the kernel; experiments depend on earlier definitions.
For local Jupyter, first install the course requirements using the Local Python steps, then use your environment’s Python to start Jupyter:
python -m pip install jupyterlab
python -m jupyter lab.\.venv\Scripts\python.exe -m pip install jupyterlab
.\.venv\Scripts\python.exe -m jupyter labSelect the downloaded welcome-cpu.ipynb file in JupyterLab. The notebook contains reference solutions; make your prediction and attempt each practice task before opening them. Restart the kernel before changing logical device setup.
The worked reference for this lesson is CPU-validated. Some references explicitly configure logical CPU devices; setting JAX_PLATFORMS does not adapt them to a TPU. Follow the execution matrix and reviewed multi-host example before attempting a target run.
For accelerator preparation, study TPU setup, observed runtime receipts, checkpointed jobs and precision and retained traces. These target paths remain unqualified on physical TPU hardware until an actual receipt is recorded. Cloud provisioning is optional for CPU learning.
Check: CPU devices: . Four input shards of shape . Global shape ; result ,,,. Device repr and JAX version vary.
Revisit the guided CPU setup · Open 19: TPU Setup. Package instructions are CPU instructions; Windows and accelerator environments need their own validation.
What you will be able to do
- Start four virtual CPU devices in a fresh process.
- Explain global shape, shard index and local shape.
- Compare row partitioning with replication.
- Diagnose divisibility and distinguish CPU practice from TPU evidence.
The problem
You can explore how JAX splits an array across devices using just your laptop. We’ll create four logical CPU devices, give each one a piece of an array, and compare the result with NumPy. Start with the setup and array/device lessons. These logical devices share your CPU: they help us learn placement, but they do not reproduce accelerator speed or memory.
The idea
Logical CPU devices let us practice how a global array is divided and addressed. They share a physical host. Treat them as a way to make placement visible, then use a real accelerator run to investigate accelerator memory, communication and speed.
Distinguish ownership from extra computing power
Suppose a global array has four rows and each logical device owns one row. The global shape still describes all four rows; a local shard describes the one row stored for that owner. Asking for the global shape and inspecting a local buffer are different operations.
The ownership heatmap assigns a category to each device. A darker device color does not mean more work or a faster device. Follow the row boundary and the device label together.
Set the logical-device configuration before JAX initializes its backend, then inspect the actual device count in a fresh process. Changing a flag after initialization does not retroactively repartition an already-running process.
Configure the runtime before it exists
Open the lesson workspace from setup and create main.py. The first block imports JAX, chooses CPU, and requests four CPU devices. Importing jax is allowed before the configuration; querying devices or creating an array can initialize the backend. That initialization is the boundary after which changing the count is too late.
Run python main.py as a fresh process. In Jupyter or Colab, restart the kernel/runtime and use Run all so this configuration is the first JAX operation. If you already ran an earlier lesson in that kernel, merely rerunning this cell cannot reliably rebuild the runtime. The explicit count check gives you a repair instruction instead of silently proceeding with one device. A terminal alternative is JAX_PLATFORMS=cpu JAX_NUM_CPU_DEVICES=4 python main.py; Windows PowerShell uses $env:JAX_PLATFORMS="cpu" and $env:JAX_NUM_CPU_DEVICES="4" before python main.py.
Distinguish logical devices from your CPU hardware
Four reported CPU devices do not mean you bought four CPUs or reserved four isolated cores. They share your computer and its resources. Each is a target JAX can place an array on. Keep the actual JAX version, device platform, process count and device count in your report so readers know what was tested.
This exercise has one controller process and four addressable devices. Multi-host JAX involves additional processes and coordination; this exercise does not test those. Even if you time an operation here, the observation belongs to this CPU setup and workload. It is distinct from whether the same partitioning is fast on a TPU.
A global array contains local pieces
The host array has shape : four examples with two values each. Mesh assigns the four devices the named axis data. P("data",None) maps the first array dimension to that mesh axis and leaves the feature dimension unpartitioned. Each local shard therefore has shape .
Use shard.index to identify its slice in the global array and shard.data to inspect its values. The global x.shape stays ; it does not become just because each device holds one row. Conversion with np.asarray(x) gathers the fully addressable global array to the host in this small single-process exercise.
Global rows [0,1] [2,3] [4,5] [6,7]
             ↓     ↓     ↓     ↓
CPU device   0     1     2     3
local shape (1,2) on every device; global shape (4,2)
Check arithmetic separately from placement
The function is elementwise: a row does not need a value from a different row. For the first row , predict ; for the final row , predict . The jit contract declares input and output placement explicitly. The NumPy check verifies all values, and shard inspections verify the intended partition. Neither alone verifies both.
block_until_ready waits for the result before reporting. It is useful when observing execution and essential for a future synchronized timing experiment, but no timings are claimed here. Four-way row partitioning requires a row count divisible by four. Try five rows deliberately, read the shape error, and choose a repair that preserves what your experiment means.
Four logical devices own four different rows
Predict before looking: Does each device hold the full array or one row?
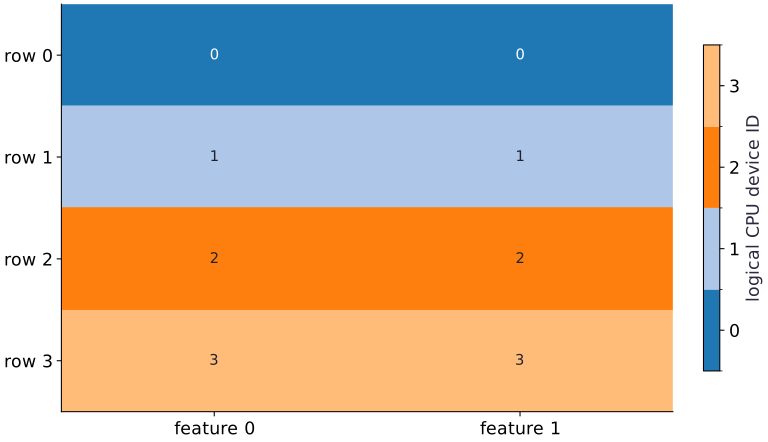
Read the figure
Each cell represents a position in the global array, and its number identifies the logical CPU device that owns that position. The colors are categories: device is not “more powerful” than device .
Both cells in row belong to device ; both cells in row belong to device , and the same pattern continues through row . Horizontal bands show that this layout partitions rows while keeping each row’s features together.
Connect it to the computation
The global shape is , so splitting its first axis across four devices gives each device a local piece with shape . This is the spatial meaning of the row partition in the code. The numbers in the figure are ownership labels, not the original array’s contents.
You can check the interpretation by locating row , feature : its owner is device . These logical devices share the host CPU. The figure establishes where values are placed, not a measured speedup or the behavior of four physical accelerators.
Open full-size figureDownload data and provenance
The notebook contains the data experiment, plotting code, and recorded figure output. Rerun it to test your changes.
Where to put & run this code: Work in phases/00-welcome/03-virtual-cpu-devices/code/main.py (or downloaded exercises/welcome-cpu.py / exercises/welcome-cpu.ipynb) and execute from the repository root with python3 phases/00-welcome/03-virtual-cpu-devices/code/main.py.
1 Start a fresh CPU runtime
Create main.py in your course workspace. Paste this block first. If using a notebook, restart its kernel before running any cell.
# Step 1 — Start a fresh CPU runtime: Configuration happens before devices() or array creation...
import jax
# Run this file in a fresh process; in a notebook restart the kernel first.
jax.config.update("jax_platforms", "cpu")
# Update state in place with the new values.
jax.config.update("jax_num_cpu_devices", 4)
import jax.numpy as jnp
import numpy as np
from jax.sharding import Mesh, NamedSharding, PartitionSpec as P
# Query the active JAX devices into `devices`.
devices = jax.devices("cpu")
# Guard input contract (`len(devices) != 4`) and fail fast if violated.
if len(devices) != 4:
    raise RuntimeError("Expected four CPU devices. Restart the notebook kernel, then Run all; do not run an earlier JAX cell first.")
# Configure multi-device placement / sharding specification (`mesh`).
mesh = Mesh(np.array(devices), ("data",))
# Configure multi-device placement / sharding specification (`rows`).
rows = NamedSharding(mesh, P("data", None))
# Configure multi-device placement / sharding specification (`replicated`).
replicated = NamedSharding(mesh, P())
Code building blocks in this step
Mesh + PartitionSpec + NamedSharding— Maps logical tensor axes onto physical device mesh axes for SPMD data, tensor, or pipeline parallelism.
Configuration happens before devices() or array creation initializes a backend. This file explicitly chooses CPU even on a GPU machine.
2 Place and compute
Append this block in the same file. Predict the shapes and values before running.
# Step 2 — Place and compute: Mesh axis names describe placement.
# Construct and reshape `host` into the target tensor dimensions.
host = np.arange(8, dtype=np.float32).reshape(4, 2)
# Place `x` explicitly onto the target JAX device.
x = jax.device_put(host, rows)
# Wrap with `jax.jit` (`y`) so XLA traces and compiles the function.
y = jax.jit(lambda a: 2 * a + 1, in_shardings=rows, out_shardings=rows)(x)
# Synchronize host execution until asynchronous device computation completes.
y.block_until_ready()
Code building blocks in this step
array.reshape(new_shape)— Reorganizes tensor axes without changing the total element count (array.size).jax.jit(fn) / @jax.jit— Tracesfnwith abstract shapes and compiles a fused XLA executable cached by input shape and dtype.Mesh + PartitionSpec + NamedSharding— Maps logical tensor axes onto physical device mesh axes for SPMD data, tensor, or pipeline parallelism.jax.block_until_ready(output)— Synchronizes with the accelerator/CPU device so asynchronous dispatch finishes before wall-clock timing.
Mesh axis names describe placement. They are separate from the numerical array dimensions.
3 Inspect and verify
Append the checks, save the file and run python main.py with the setup lesson environment.
# Step 3 — Inspect and verify: Assertions compare against host calculations or hand-derived...
print("JAX version:", jax.__version__)
print("CPU devices:", len(devices))
for shard in x.addressable_shards:
    print("Device", shard.device.id, "index", shard.index, "values", np.asarray(shard.data))
# Convert `` to a host NumPy array for inspection or verification.
np.testing.assert_array_equal(np.asarray(y), 2 * host + 1)
assert len(x.addressable_shards) == 4
# Check tensor shape invariant: `all(shard.data.shape == (1, 2) for shard in x.addressable_shards)`
assert all(shard.data.shape == (1, 2) for shard in x.addressable_shards)
print("Global shape:", x.shape, "result:", np.asarray(y).tolist())
Code building blocks in this step
np.asarray(...)— Callnp.asarraywith your updated parameters or inputs from this lesson's workspace.testing.assert_array_equal(...)— Calltesting.assert_array_equalwith your updated parameters or inputs from this lesson's workspace.assert condition— Verify that the observed output shape, status, or numerical value satisfies the contract.
Assertions compare against host calculations or hand-derived values; printing a sharding object alone is separate from correctness.
View the cumulative build in main.py
These blocks append in order to the same file.
# Step 1 — Start a fresh CPU runtime: Configuration happens before devices() or array creation...
import jax
# Run this file in a fresh process; in a notebook restart the kernel first.
jax.config.update("jax_platforms", "cpu")
# Update state in place with the new values.
jax.config.update("jax_num_cpu_devices", 4)
import jax.numpy as jnp
import numpy as np
from jax.sharding import Mesh, NamedSharding, PartitionSpec as P
# Query the active JAX devices into `devices`.
devices = jax.devices("cpu")
# Guard input contract (`len(devices) != 4`) and fail fast if violated.
if len(devices) != 4:
    raise RuntimeError("Expected four CPU devices. Restart the notebook kernel, then Run all; do not run an earlier JAX cell first.")
# Configure multi-device placement / sharding specification (`mesh`).
mesh = Mesh(np.array(devices), ("data",))
# Configure multi-device placement / sharding specification (`rows`).
rows = NamedSharding(mesh, P("data", None))
# Configure multi-device placement / sharding specification (`replicated`).
replicated = NamedSharding(mesh, P())

# Step 2 — Place and compute: Mesh axis names describe placement.
# Construct and reshape `host` into the target tensor dimensions.
host = np.arange(8, dtype=np.float32).reshape(4, 2)
# Place `x` explicitly onto the target JAX device.
x = jax.device_put(host, rows)
# Wrap with `jax.jit` (`y`) so XLA traces and compiles the function.
y = jax.jit(lambda a: 2 * a + 1, in_shardings=rows, out_shardings=rows)(x)
# Synchronize host execution until asynchronous device computation completes.
y.block_until_ready()

# Step 3 — Inspect and verify: Assertions compare against host calculations or hand-derived...
print("JAX version:", jax.__version__)
print("CPU devices:", len(devices))
for shard in x.addressable_shards:
    print("Device", shard.device.id, "index", shard.index, "values", np.asarray(shard.data))
# Convert `` to a host NumPy array for inspection or verification.
np.testing.assert_array_equal(np.asarray(y), 2 * host + 1)
assert len(x.addressable_shards) == 4
# Check tensor shape invariant: `all(shard.data.shape == (1, 2) for shard in x.addressable_shards)`
assert all(shard.data.shape == (1, 2) for shard in x.addressable_shards)
print("Global shape:", x.shape, "result:", np.asarray(y).tolist())
Run the example
python3 phases/00-welcome/03-virtual-cpu-devices/code/main.pyAbout this command
This shortcut uses an activated macOS/Linux course environment in the repository folder. For Windows, use the explicit interpreter command in “Setup help” above. The script includes worked examples and reference solutions.
Inspect the complete assembled example
# Step 1 — Start a fresh CPU runtime: Configuration happens before devices() or array creation...
import jax
# Run this file in a fresh process; in a notebook restart the kernel first.
jax.config.update("jax_platforms", "cpu")
# Update state in place with the new values.
jax.config.update("jax_num_cpu_devices", 4)
import jax.numpy as jnp
import numpy as np
from jax.sharding import Mesh, NamedSharding, PartitionSpec as P
# Query the active JAX devices into `devices`.
devices = jax.devices("cpu")
# Guard input contract (`len(devices) != 4`) and fail fast if violated.
if len(devices) != 4:
    raise RuntimeError("Expected four CPU devices. Restart the notebook kernel, then Run all; do not run an earlier JAX cell first.")
# Configure multi-device placement / sharding specification (`mesh`).
mesh = Mesh(np.array(devices), ("data",))
# Configure multi-device placement / sharding specification (`rows`).
rows = NamedSharding(mesh, P("data", None))
# Configure multi-device placement / sharding specification (`replicated`).
replicated = NamedSharding(mesh, P())

# Step 2 — Place and compute: Mesh axis names describe placement.
# Construct and reshape `host` into the target tensor dimensions.
host = np.arange(8, dtype=np.float32).reshape(4, 2)
# Place `x` explicitly onto the target JAX device.
x = jax.device_put(host, rows)
# Wrap with `jax.jit` (`y`) so XLA traces and compiles the function.
y = jax.jit(lambda a: 2 * a + 1, in_shardings=rows, out_shardings=rows)(x)
# Synchronize host execution until asynchronous device computation completes.
y.block_until_ready()

# Step 3 — Inspect and verify: Assertions compare against host calculations or hand-derived...
print("JAX version:", jax.__version__)
print("CPU devices:", len(devices))
for shard in x.addressable_shards:
    print("Device", shard.device.id, "index", shard.index, "values", np.asarray(shard.data))
# Convert `` to a host NumPy array for inspection or verification.
np.testing.assert_array_equal(np.asarray(y), 2 * host + 1)
assert len(x.addressable_shards) == 4
# Check tensor shape invariant: `all(shard.data.shape == (1, 2) for shard in x.addressable_shards)`
assert all(shard.data.shape == (1, 2) for shard in x.addressable_shards)
print("Global shape:", x.shape, "result:", np.asarray(y).tolist())
Expected result: CPU devices: . Four input shards of shape . Global shape ; result ,,,. Device repr and JAX version vary.
Recorded reference execution
Reference output captured from executing the complete lesson script (code/main.py) and its assertions in the course CPU environment.
JAX version: 0.9.2
CPU devices: 4
Device 0 index (slice(0, 1, None), slice(None, None, None)) values [[0. 1.]]
Device 1 index (slice(1, 2, None), slice(None, None, None)) values [[2. 3.]]
Device 2 index (slice(2, 3, None), slice(None, None, None)) values [[4. 5.]]
Device 3 index (slice(3, 4, None), slice(None, None, None)) values [[6. 7.]]
Global shape: (4, 2) result: [[1.0, 3.0], [5.0, 7.0], [9.0, 11.0], [13.0, 15.0]]
Negative input result: [[-3.0, -5.0], [-7.0, -9.0], [-11.0, -13.0], [-15.0, -17.0]]
Replicated local shapes: [(4, 2), (4, 2), (4, 2), (4, 2)]
Expected indivisible row dimension
Expected indivisible row dimension
PASS: welcome-cpu
Download execution record · The notebook includes executed cells and figure outputs. Compare your run with these values; timings depend on the machine.
Keep the shape, change the values
# Experiment — Keep the shape, change the values: Placement follows the declared shape/specification, not the...
negative = -host - 2
# Place `negative_x` explicitly onto the target JAX device.
negative_x = jax.device_put(negative, rows)
# Wrap with `jax.jit` (`negative_y`) so XLA traces and compiles the function.
negative_y = jax.jit(lambda a: 2*a+1, in_shardings=rows, out_shardings=rows)(negative_x)
# Convert `` to a host NumPy array for inspection or verification.
np.testing.assert_array_equal(np.asarray(negative_y), 2*negative+1)
# Check tensor shape invariant: `all(s.data.shape == (1,2) for s in negative_x.addressable_shards)`
assert all(s.data.shape == (1,2) for s in negative_x.addressable_shards)
print("Negative input result:", np.asarray(negative_y).tolist())
Expected: Result ,,,; local shapes remain .
Placement follows the declared shape/specification, not the signs or magnitudes of array elements.
Replicate instead of partitioning
# Experiment — Replicate instead of partitioning: Replication stores full copies.
copies = jax.device_put(host, replicated)
assert copies.is_fully_replicated
assert len(copies.addressable_shards) == 4
for shard in copies.addressable_shards:
    # Convert `` to a host NumPy array for inspection or verification.
    np.testing.assert_array_equal(np.asarray(shard.data), host)
print("Replicated local shapes:", [s.data.shape for s in copies.addressable_shards])
Expected: Four local arrays of shape , each containing the entire input.
Replication stores full copies. A global array shape alone cannot tell you how much of it lives on each device.
Make it yours
Where to put your code: Append your solution at the bottom of phases/00-welcome/03-virtual-cpu-devices/code/main.py (or inside the Make it yours cell of exercises/welcome-cpu.ipynb) and run python3 phases/00-welcome/03-virtual-cpu-devices/code/main.py to verify your prediction before opening the reference solution.
Predict and verify the per-device shapes for twelve rows, then demonstrate how replication repairs an indivisible five-row placement without deleting data.
Show a writing guide and starter scaffold
How to write this exercise code: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
array.reshape(new_shape)— Reorganizes tensor axes without changing the total element count (array.size).jax.jit(fn) / @jax.jit— Tracesfnwith abstract shapes and compiles a fused XLA executable cached by input shape and dtype.Mesh + PartitionSpec + NamedSharding— Maps logical tensor axes onto physical device mesh axes for SPMD data, tensor, or pipeline parallelism.
2. Step-by-step implementation plan:
- Construct and reshape
twelveinto the target tensor dimensions. - Place
zexplicitly onto the target JAX device. - Wrap with
jax.jit(z2) so XLA traces and compiles the function. - Check tensor shape invariant:
all(s.data.shape == (3,2) for s in z2.addressable_shards) - Convert
to a host NumPy array for inspection or verification.
# Exercise solution: Predict and verify the per-device shapes for twelve rows, then...
# Construct and reshape `twelve` into the target tensor dimensions.
twelve = np.arange(...)  # TODO: compute twelve
# Place `z` explicitly onto the target JAX device.
z = jax.device_put(...)  # TODO: compute z
# Wrap with `jax.jit` (`z2`) so XLA traces and compiles the function.
z2 = jax.jit(...)  # TODO: compute z2
# Check tensor shape invariant: `all(s.data.shape == (3,2) for s in z2.addressable_shards)`
assert all(s.data.shape  # TODO: complete assertion check
for shard in z2.addressable_shards:
    # Convert `` to a host NumPy array for inspection or verification.
    np.testing.assert_array_equal(np.asarray(shard.data), (twelve*twelve)[shard.index])

# Construct and reshape `uneven` into the target tensor dimensions.
uneven = np.arange(...)  # TODO: compute uneven
# Run the boundary check and catch the expected exception:
try:
    jax.device_put(uneven, rows)
except ValueError:
    print("Expected indivisible row dimension")
else:
    raise AssertionError("Expected divisibility failure")
# Place `fixed` explicitly onto the target JAX device.
fixed = jax.device_put(...)  # TODO: compute fixed
# Convert `` to a host NumPy array for inspection or verification.
np.testing.assert_array_equal(np.asarray(fixed), uneven)
assert fixed.is_fully_replicated  # TODO: complete assertion check
Reveal the reference solution
# Exercise solution: Predict and verify the per-device shapes for twelve rows, then...
# Construct and reshape `twelve` into the target tensor dimensions.
twelve = np.arange(24,dtype=np.float32).reshape(12,2)
# Place `z` explicitly onto the target JAX device.
z = jax.device_put(twelve, rows)
# Wrap with `jax.jit` (`z2`) so XLA traces and compiles the function.
z2 = jax.jit(lambda a:a*a, in_shardings=rows, out_shardings=rows)(z)
# Check tensor shape invariant: `all(s.data.shape == (3,2) for s in z2.addressable_shards)`
assert all(s.data.shape == (3,2) for s in z2.addressable_shards)
for shard in z2.addressable_shards:
    # Convert `` to a host NumPy array for inspection or verification.
    np.testing.assert_array_equal(np.asarray(shard.data), (twelve*twelve)[shard.index])

# Construct and reshape `uneven` into the target tensor dimensions.
uneven = np.arange(10,dtype=np.float32).reshape(5,2)
# Run the boundary check and catch the expected exception:
try:
    jax.device_put(uneven, rows)
except ValueError:
    print("Expected indivisible row dimension")
else:
    raise AssertionError("Expected divisibility failure")
# Place `fixed` explicitly onto the target JAX device.
fixed = jax.device_put(uneven, replicated)
# Convert `` to a host NumPy array for inspection or verification.
np.testing.assert_array_equal(np.asarray(fixed), uneven)
assert fixed.is_fully_replicated
Move from four rows to twelve
Challenge
Create twelve two-feature rows with values through . Predict shard shape and check every slice of a squared output.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
array.reshape(new_shape)— Reorganizes tensor axes without changing the total element count (array.size).jax.jit(fn) / @jax.jit— Tracesfnwith abstract shapes and compiles a fused XLA executable cached by input shape and dtype.Mesh + PartitionSpec + NamedSharding— Maps logical tensor axes onto physical device mesh axes for SPMD data, tensor, or pipeline parallelism.
2. Step-by-step implementation plan:
- Construct and reshape
twelveinto the target tensor dimensions. - Place
zexplicitly onto the target JAX device. - Wrap with
jax.jit(z2) so XLA traces and compiles the function. - Check tensor shape invariant:
all(s.data.shape == (3,2) for s in z2.addressable_shards) - Convert
to a host NumPy array for inspection or verification.
# Move from four rows to twelve (Challenge): The twelve rows split into four groups of three.
# Construct and reshape `twelve` into the target tensor dimensions.
twelve = np.arange(...)  # TODO: compute twelve
# Place `z` explicitly onto the target JAX device.
z = jax.device_put(...)  # TODO: compute z
# Wrap with `jax.jit` (`z2`) so XLA traces and compiles the function.
z2 = jax.jit(...)  # TODO: compute z2
# Check tensor shape invariant: `all(s.data.shape == (3,2) for s in z2.addressable_shards)`
assert all(s.data.shape  # TODO: complete assertion check
for shard in z2.addressable_shards:
    # Convert `` to a host NumPy array for inspection or verification.
    np.testing.assert_array_equal(np.asarray(shard.data), (twelve*twelve)[shard.index])
Show a hint
Use each shard index to select the corresponding NumPy reference slice.
Reveal reference solution and reasoning
# Move from four rows to twelve (Challenge): The twelve rows split into four groups of three.
# Construct and reshape `twelve` into the target tensor dimensions.
twelve = np.arange(24,dtype=np.float32).reshape(12,2)
# Place `z` explicitly onto the target JAX device.
z = jax.device_put(twelve, rows)
# Wrap with `jax.jit` (`z2`) so XLA traces and compiles the function.
z2 = jax.jit(lambda a:a*a, in_shardings=rows, out_shardings=rows)(z)
# Check tensor shape invariant: `all(s.data.shape == (3,2) for s in z2.addressable_shards)`
assert all(s.data.shape == (3,2) for s in z2.addressable_shards)
for shard in z2.addressable_shards:
    # Convert `` to a host NumPy array for inspection or verification.
    np.testing.assert_array_equal(np.asarray(shard.data), (twelve*twelve)[shard.index])
The twelve rows split into four groups of three. Index-based comparisons establish that the right values occupy each piece, rather than checking only a total.
Repair a batch that does not divide evenly
Challenge
Place a array with the same row sharding. Capture the failure. Repair this placement demonstration by replicating it, and explain why that does not prove the partitioned algorithm supports uneven batches.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
array.reshape(new_shape)— Reorganizes tensor axes without changing the total element count (array.size).Mesh + PartitionSpec + NamedSharding— Maps logical tensor axes onto physical device mesh axes for SPMD data, tensor, or pipeline parallelism.
2. Step-by-step implementation plan:
- Construct and reshape
uneveninto the target tensor dimensions. - Run the boundary check and catch the expected exception:
- Place
fixedexplicitly onto the target JAX device. - Convert
to a host NumPy array for inspection or verification.
# Repair a batch that does not divide evenly (Challenge): Five rows cannot be evenly split across the four-way data axis.
# Construct and reshape `uneven` into the target tensor dimensions.
uneven = np.arange(...)  # TODO: compute uneven
# Run the boundary check and catch the expected exception:
try:
    jax.device_put(uneven, rows)
except ValueError:
    print("Expected indivisible row dimension")
else:
    raise AssertionError("Expected divisibility failure")
# Place `fixed` explicitly onto the target JAX device.
fixed = jax.device_put(...)  # TODO: compute fixed
# Convert `` to a host NumPy array for inspection or verification.
np.testing.assert_array_equal(np.asarray(fixed), uneven)
assert fixed.is_fully_replicated  # TODO: complete assertion check
Show a hint
Do not drop a row to hide the error.
Reveal reference solution and reasoning
# Repair a batch that does not divide evenly (Challenge): Five rows cannot be evenly split across the four-way data axis.
# Construct and reshape `uneven` into the target tensor dimensions.
uneven = np.arange(10,dtype=np.float32).reshape(5,2)
# Run the boundary check and catch the expected exception:
try:
    jax.device_put(uneven, rows)
except ValueError:
    print("Expected indivisible row dimension")
else:
    raise AssertionError("Expected divisibility failure")
# Place `fixed` explicitly onto the target JAX device.
fixed = jax.device_put(uneven, replicated)
# Convert `` to a host NumPy array for inspection or verification.
np.testing.assert_array_equal(np.asarray(fixed), uneven)
assert fixed.is_fully_replicated
Five rows cannot be evenly split across the four-way data axis. Replication preserves all observations but changes the memory/communication plan; padding requires a mask when computing means.
Diagnose the result
Five rows cannot be evenly split across the four-way data axis. Replication preserves all observations but changes the memory/communication plan; padding requires a mask when computing means.
Carry forward
- Configure the runtime before it exists
- Distinguish logical devices from your CPU hardware
- A global array contains local pieces
- Check arithmetic separately from placement
Keep your evidence
Keep package/device reports, global and local shapes, shard index/value tables, NumPy comparisons, changed-shape predictions, and the five-row failure/repair. State that the run uses one host and does not validate TPU performance.
Save your modified code, its output, and an explanation of your prediction. Checkpoint answers and exercise evidence are tracked separately.
Saved in this browser. Export or back up your portfolio anytime in My learning.
Verified on local CPU. Stage to a Cloud TPU VM via Cloud TPU setup to record accelerator execution receipts (TODO: add automated Cloud TPU CI execution receipts).