 JAX Pathways
Phase 12 / Reinforcement learning
Batch environments and scan rollouts
Revision v0.7.0 · Updated since your last visit. Review the changes; your progress is saved.
Lesson · about 85 minutes · CPU practice
Build a scan over vmapped transitions with explicit key ownership. Reconstruct episode returns and reward-to-go from padded trajectories.
Phase study guide: preparation, milestones and project evidence
Before you start
Before this: Write a functional environment
Hardware: CPU
Setup help: Python, notebook, or Cloud TPU VM
Use the tested CPU packages (the recorded environment uses Python 3.14.3). Other Python versions and accelerator environments require separate checks. The optional Cloud TPU specialization explains the target-specific execution boundaries. Logical CPU devices practice partitioning; they do not simulate TPU performance.
Download the repository ZIP or use your existing checkout. Extract it and open a terminal in the folder containing requirements-cpu.txt. The beginner ZIP is separate; these lessons use the full repository folder.
python3 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements-cpu.txtpy -3 -m venv .venv
.\.venv\Scripts\python.exe -m pip install -r requirements-cpu.txtAfter activation, run the complete worked example from that same folder:
python phases/12-rl/02-batch-environments-and-scan-rollouts/code/main.py.\.venv\Scripts\python.exe phases/12-rl/02-batch-environments-and-scan-rollouts/code/main.pyFor an incremental build, create main.py in your own practice folder, append each build block in order, and run python main.py with this environment active. Keep that file separate from the downloaded reference solution.
Download this lesson’s notebook. Open it with a Python kernel using the course environment. Run cells from the top after restarting the kernel; experiments depend on earlier definitions.
For local Jupyter, first install the course requirements using the Local Python steps, then use your environment’s Python to start Jupyter:
python -m pip install jupyterlab
python -m jupyter lab.\.venv\Scripts\python.exe -m pip install jupyterlab
.\.venv\Scripts\python.exe -m jupyter labSelect the downloaded rl-02.ipynb file in JupyterLab. The notebook contains reference solutions; make your prediction and attempt each practice task before opening them. Restart the kernel before changing logical device setup.
The worked reference for this lesson is CPU-validated. Some references explicitly configure logical CPU devices; setting JAX_PLATFORMS does not adapt them to a TPU. Follow the execution matrix and reviewed multi-host example before attempting a target run.
For accelerator preparation, study TPU setup, observed runtime receipts, checkpointed jobs and precision and retained traces. These target paths remain unqualified on physical TPU hardware until an actual receipt is recorded. Cloud provisioning is optional for CPU learning.
Check: The trajectory has the stated time and environment axes, exactly one ending event per episode, and zero reward on every padded row.
Revisit the guided CPU setup · Open 19: TPU Setup. Package instructions are CPU instructions; Windows and accelerator environments need their own validation.
What you will be able to do
- Build a scan over vmapped transitions with explicit key ownership.
- Reconstruct episode returns and reward-to-go from padded trajectories.
- Verify the live-transition mask and distinguish batch dimensions from time dimensions.
The problem
One episode is easy to inspect, but an agent needs many experiences. How do we collect a batch without mixing time, environments or random streams? We will turn the previous transition into a fixed-shape rollout and prove that its padded rows cannot become training evidence.
The idea
Batched rollouts put independent environments on one axis and time on another. Some environments finish earlier, so masks describe which transitions remain meaningful while arrays keep fixed shapes.
Keep the array shape fixed while activity changes
Draw one environment per row and time across columns. Mark the transition that terminates an episode, then mark later padding separately. The terminal transition can still earn reward; masking it out too early loses part of the episode.
Carry the next state and activity information explicitly. If the implementation resets finished environments, distinguish that contract from absorbing padding instead of mixing them in one explanation.
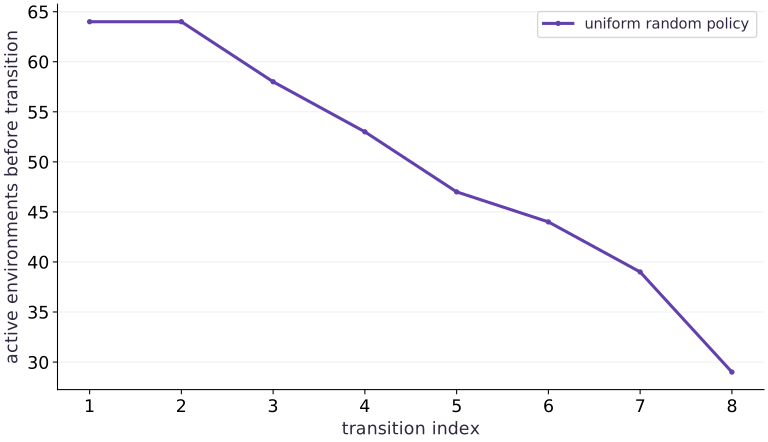
The active-count curve decreases while the tensor shape stays fixed. It measures active environments, not shrinking allocation. Verify one environment independently, then permute the batch to check that unrelated trajectories stay independent.
A terminal transition still counts
Predict: Should every cell after the first done flag be treated identically to the transition that caused done?
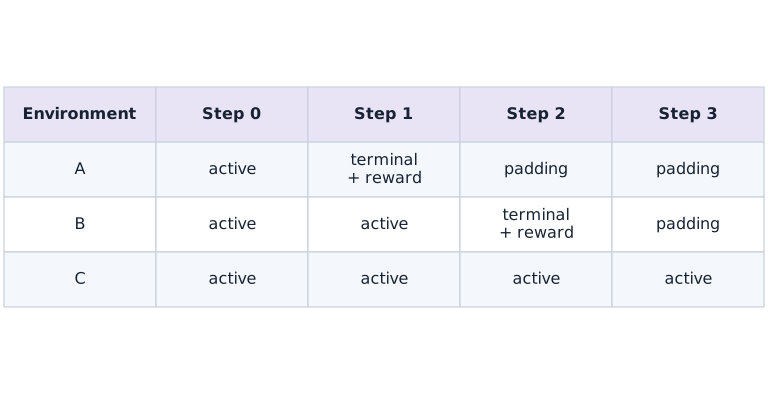
Each row is one environment. A terminating transition can still earn reward; later cells are padding under this absorbing-state contract. Tensor length stays fixed while activity changes. This is a conceptual rollout example, not an auto-reset implementation.
Give each axis one meaning
For and , the reward array has shape . Summing axis zero gives one return per episode. Summing axis one gives total reward at each time index across the batch, a different statistic. vmap maps reset and step over environments; scan threads the complete batch of states through time. The carry has the same structure, shapes and dtypes at every iteration.
Split randomness where ownership changes
First split a reset key from an action key. Split reset keys across the environments. Split action keys across the time steps, then across environments. A scalar reset key broadcast to all environments would create correlated starts. An action key reused at every step would replay draws. Deterministic transitions do not need an extra key, so their signature stays simple.
Store the behavior policy before changing it
Each position has a policy logit . Applying the sigmoid gives the probability of moving right; the left probability is its complement. A sampled action is discrete, so we will not differentiate through action sampling. Instead, we store its log probability under the behavior policy. Stable log-sigmoid avoids taking a logarithm of a probability rounded to zero.
A final transition is still a learning example
The active mask is computed from the state before step. Therefore the action that reaches the goal is active and retains its reward. Only subsequent rows are padding. Masking with the next state would delete the successful action itself. We store the final observation in the returned state and do not replace it with a fresh start. This collector handles one finite episode per environment, not an endless auto-reset stream.
Credit each action with rewards that follow it
Reward-to-go sums rewards from the current time onward. For rewards , targets are . The first action can influence all later rewards; the last successful action is credited with the goal reward only. We reverse the time axis, take a cumulative sum, and reverse it back. There is no value bootstrap here because these are complete finite-horizon episodes.
The live batch shrinks while the array shape stays fixed
Predict before looking: Should every row contain the same number of active environments?
Read the figure
The horizontal axis is the transition index; the vertical axis counts environments active before that transition. The first value is . The count never rises because we do not reset inside a rollout. Decreases show episodes reaching the goal; episodes still active on the final row will either finish or time out on that row. In the recorded seed, the first two counts are both : even the nearer starting position needs two actions to reach the goal. The third count is , and the last is . The unchanged first pair is therefore expected, not a stalled loop.
Connect it to the computation
This curve is not reward or policy quality: a fast-ending policy could succeed, fail or exploit a termination bug in a different task. Here the transition tests establish that early endings are goals. The fixed reward array retains later rows, but their active flags are false. Changing the seed can move individual counts while preserving these invariants.
Open full-size figureDownload data and provenance
The notebook contains the data experiment, plotting code, and recorded figure output. Rerun it to test your changes.
Where to put & run this code: Work in phases/12-rl/02-batch-environments-and-scan-rollouts/code/main.py (or downloaded exercises/rl-02.py / exercises/rl-02.ipynb) and execute from the repository root with python3 phases/12-rl/02-batch-environments-and-scan-rollouts/code/main.py.
1 Reuse the verified environment
Create main.py with this block. Run python3 main.py in the course CPU environment.
# Step 1: Reuse the verified environment
"""Finite-horizon tabular policy training. CPU teaching environment, not a benchmark."""
from functools import partial
from typing import NamedTuple
import jax
import jax.numpy as jnp
import numpy as np


# Define `State` module / container with explicit state and forward pass:
class State(NamedTuple):
    # Execute `position: jax.Array`
    position: jax.Array
    # Execute `elapsed: jax.Array`
    elapsed: jax.Array
    # Execute `done: jax.Array`
    done: jax.Array


def reset(key):
    """Start uniformly at position 0 or 1; goal is position 3."""
    return State(jax.random.randint(key, (), 0, 2), jnp.int32(0), jnp.bool_(False))


def step(state, action, horizon=8):
    """Action 0: left, 1: right. Caller supplies binary action and positive horizon.

    Returns next state, reward, termination event, truncation event. Finished
    states absorb without more rewards/events. No implicit reset or lost final observation.
    """
    active = ~state.done
    # Combine or mask array elements to form `proposed`.
    proposed = jnp.clip(state.position + 2 * action - 1, 0, 3)
    # Combine or mask array elements to form `position`.
    position = jnp.where(active, proposed, state.position)
    elapsed = state.elapsed + active.astype(jnp.int32)
    terminated = active & (position == 3)
    truncated = active & ~terminated & (elapsed >= horizon)
    # Combine or mask array elements to form `reward`.
    reward = jnp.where(active, jnp.where(terminated, 1., -.01), 0.)
    return State(position, elapsed, state.done | terminated | truncated), reward, terminated, truncated
Code building blocks in this step
jax.random.PRNGKey(seed) & jax.random.split(key)— Manages explicit, stateless PRNG keys—always split a key before passing subkeys into independent random draws.
Keep the state and ending contract identical to the previous lesson.
2 Collect a batch and compute targets
Append this block to main.py. Run python3 main.py in the course CPU environment.
# Step 2 — Collect a batch and compute targets: scan emits time-major arrays; vmap keeps environments independent...
def log_probability(theta, observations, actions):
    logits = theta[jnp.minimum(observations, 2)]
    return jnp.where(actions == 1, jax.nn.log_sigmoid(logits), jax.nn.log_sigmoid(-logits))


# Define and JIT-compile `rollout(theta, key, batch_size, horizon)` so XLA traces and fuses the operations:
@partial(jax.jit, static_argnames=('batch_size', 'horizon'))
def rollout(theta, key, batch_size=256, horizon=8):
    # Create or split explicit PRNG key(s) (`(reset_key, action_key)`) for reproducible randomness.
    reset_key, action_key = jax.random.split(key)
    # Create or split explicit PRNG key(s) (`states`) for reproducible randomness.
    states = jax.vmap(reset)(jax.random.split(reset_key, batch_size))
    # Create or split explicit PRNG key(s) (`time_keys`) for reproducible randomness.
    time_keys = jax.random.split(action_key, horizon)
    def body(states, time_key):
        observations = states.position
        # Split the PRNG key deterministically into independent subkeys (`keys`).
        keys = jax.random.split(time_key, batch_size)
        probabilities = jax.nn.sigmoid(theta[jnp.minimum(observations, 2)])
        # Draw pseudorandom samples for `actions` using the explicit RNG state.
        actions = jax.vmap(jax.random.bernoulli)(keys, probabilities).astype(jnp.int32)
        # Vectorize across the batch dimension without a Python loop (`(next_states, rewards, terminated, truncated)`).
        next_states, rewards, terminated, truncated = jax.vmap(
            lambda s, a: step(s, a, horizon))(states, actions)
        record = dict(observation=observations, action=actions, reward=rewards,
                      active=~states.done, terminated=terminated, truncated=truncated,
                      old_logp=log_probability(theta, observations, actions))
        return next_states, record
    # Run a compiled sequential scan over the time/step axis (`(final, records)`).
    final, records = jax.lax.scan(body, states, time_keys)
    return final, records


def returns_to_go(rewards):
    """Undiscounted finite-episode objective; rewards after done are already zero."""
    return jnp.cumsum(rewards[::-1], axis=0)[::-1]
Code building blocks in this step
jax.vmap(fn, in_axes=..., out_axes=...)— Vectorizes a single-example function across a batch axis without writing a Python loop.jax.jit(fn) / @jax.jit— Tracesfnwith abstract shapes and compiles a fused XLA executable cached by input shape and dtype.jax.lax.scan(step_fn, init_carry, xs, length=...)— Compiles a sequential loop wherestep_fn(carry, x)returns(next_carry, y), returning(final_carry, stacked_ys).jax.random.PRNGKey(seed) & jax.random.split(key)— Manages explicit, stateless PRNG keys—always split a key before passing subkeys into independent random draws.
scan emits time-major arrays; vmap keeps environments independent within each time step.
3 Check shapes and episode boundaries
Append this block to main.py. Run python3 main.py in the course CPU environment.
# Step 3 — Check shapes and episode boundaries: Exactly one ending event and zero padded rewards are stronger...
theta = jnp.zeros(3)
# Create or split explicit PRNG key(s) (`(final, records)`) for reproducible randomness.
final, records = rollout(theta, jax.random.key(5), batch_size=64, horizon=8)
# Check tensor shape invariant: `records['reward'].shape == (8`
assert records['reward'].shape == (8, 64)
assert bool(final.done.all())
assert bool(jnp.all(jnp.sum(records['terminated'] | records['truncated'], axis=0) == 1))
assert bool(jnp.all(jnp.where(records['active'], 0., records['reward']) == 0.))
# Reduce along axis=0 to compute `episode_returns`.
episode_returns = records['reward'].sum(axis=0)
print('return mean:', float(episode_returns.mean()))
print('active environments by transition:', records['active'].sum(axis=1))
Code building blocks in this step
jnp.zeros / jnp.ones(shape, dtype=...)— Allocates a tensor of the givenshapeinitialized with constants.x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jax.random.PRNGKey(seed) & jax.random.split(key)— Manages explicit, stateless PRNG keys—always split a key before passing subkeys into independent random draws.
Exactly one ending event and zero padded rewards are stronger checks than a plausible mean return.
View the cumulative build in main.py
These blocks append in order to the same file.
# Step 1: Reuse the verified environment
"""Finite-horizon tabular policy training. CPU teaching environment, not a benchmark."""
from functools import partial
from typing import NamedTuple
import jax
import jax.numpy as jnp
import numpy as np


# Define `State` module / container with explicit state and forward pass:
class State(NamedTuple):
    # Execute `position: jax.Array`
    position: jax.Array
    # Execute `elapsed: jax.Array`
    elapsed: jax.Array
    # Execute `done: jax.Array`
    done: jax.Array


def reset(key):
    """Start uniformly at position 0 or 1; goal is position 3."""
    return State(jax.random.randint(key, (), 0, 2), jnp.int32(0), jnp.bool_(False))


def step(state, action, horizon=8):
    """Action 0: left, 1: right. Caller supplies binary action and positive horizon.

    Returns next state, reward, termination event, truncation event. Finished
    states absorb without more rewards/events. No implicit reset or lost final observation.
    """
    active = ~state.done
    # Combine or mask array elements to form `proposed`.
    proposed = jnp.clip(state.position + 2 * action - 1, 0, 3)
    # Combine or mask array elements to form `position`.
    position = jnp.where(active, proposed, state.position)
    elapsed = state.elapsed + active.astype(jnp.int32)
    terminated = active & (position == 3)
    truncated = active & ~terminated & (elapsed >= horizon)
    # Combine or mask array elements to form `reward`.
    reward = jnp.where(active, jnp.where(terminated, 1., -.01), 0.)
    return State(position, elapsed, state.done | terminated | truncated), reward, terminated, truncated

# Step 2 — Collect a batch and compute targets: scan emits time-major arrays; vmap keeps environments independent...
def log_probability(theta, observations, actions):
    logits = theta[jnp.minimum(observations, 2)]
    return jnp.where(actions == 1, jax.nn.log_sigmoid(logits), jax.nn.log_sigmoid(-logits))


# Define and JIT-compile `rollout(theta, key, batch_size, horizon)` so XLA traces and fuses the operations:
@partial(jax.jit, static_argnames=('batch_size', 'horizon'))
def rollout(theta, key, batch_size=256, horizon=8):
    # Create or split explicit PRNG key(s) (`(reset_key, action_key)`) for reproducible randomness.
    reset_key, action_key = jax.random.split(key)
    # Create or split explicit PRNG key(s) (`states`) for reproducible randomness.
    states = jax.vmap(reset)(jax.random.split(reset_key, batch_size))
    # Create or split explicit PRNG key(s) (`time_keys`) for reproducible randomness.
    time_keys = jax.random.split(action_key, horizon)
    def body(states, time_key):
        observations = states.position
        # Split the PRNG key deterministically into independent subkeys (`keys`).
        keys = jax.random.split(time_key, batch_size)
        probabilities = jax.nn.sigmoid(theta[jnp.minimum(observations, 2)])
        # Draw pseudorandom samples for `actions` using the explicit RNG state.
        actions = jax.vmap(jax.random.bernoulli)(keys, probabilities).astype(jnp.int32)
        # Vectorize across the batch dimension without a Python loop (`(next_states, rewards, terminated, truncated)`).
        next_states, rewards, terminated, truncated = jax.vmap(
            lambda s, a: step(s, a, horizon))(states, actions)
        record = dict(observation=observations, action=actions, reward=rewards,
                      active=~states.done, terminated=terminated, truncated=truncated,
                      old_logp=log_probability(theta, observations, actions))
        return next_states, record
    # Run a compiled sequential scan over the time/step axis (`(final, records)`).
    final, records = jax.lax.scan(body, states, time_keys)
    return final, records


def returns_to_go(rewards):
    """Undiscounted finite-episode objective; rewards after done are already zero."""
    return jnp.cumsum(rewards[::-1], axis=0)[::-1]

# Step 3 — Check shapes and episode boundaries: Exactly one ending event and zero padded rewards are stronger...
theta = jnp.zeros(3)
# Create or split explicit PRNG key(s) (`(final, records)`) for reproducible randomness.
final, records = rollout(theta, jax.random.key(5), batch_size=64, horizon=8)
# Check tensor shape invariant: `records['reward'].shape == (8`
assert records['reward'].shape == (8, 64)
assert bool(final.done.all())
assert bool(jnp.all(jnp.sum(records['terminated'] | records['truncated'], axis=0) == 1))
assert bool(jnp.all(jnp.where(records['active'], 0., records['reward']) == 0.))
# Reduce along axis=0 to compute `episode_returns`.
episode_returns = records['reward'].sum(axis=0)
print('return mean:', float(episode_returns.mean()))
print('active environments by transition:', records['active'].sum(axis=1))
Run the example
python3 phases/12-rl/02-batch-environments-and-scan-rollouts/code/main.pyAbout this command
This shortcut uses an activated macOS/Linux course environment in the repository folder. For Windows, use the explicit interpreter command in “Setup help” above. The script includes worked examples and reference solutions.
Inspect the complete assembled example
# Complete runnable example (rl-02)
"""Finite-horizon tabular policy training. CPU teaching environment, not a benchmark."""
from functools import partial
from typing import NamedTuple
import jax
import jax.numpy as jnp
import numpy as np


# Define `State` module / container with explicit state and forward pass:
class State(NamedTuple):
    # Execute `position: jax.Array`
    position: jax.Array
    # Execute `elapsed: jax.Array`
    elapsed: jax.Array
    # Execute `done: jax.Array`
    done: jax.Array


def reset(key):
    """Start uniformly at position 0 or 1; goal is position 3."""
    return State(jax.random.randint(key, (), 0, 2), jnp.int32(0), jnp.bool_(False))


def step(state, action, horizon=8):
    """Action 0: left, 1: right. Caller supplies binary action and positive horizon.

    Returns next state, reward, termination event, truncation event. Finished
    states absorb without more rewards/events. No implicit reset or lost final observation.
    """
    active = ~state.done
    # Combine or mask array elements to form `proposed`.
    proposed = jnp.clip(state.position + 2 * action - 1, 0, 3)
    # Combine or mask array elements to form `position`.
    position = jnp.where(active, proposed, state.position)
    elapsed = state.elapsed + active.astype(jnp.int32)
    terminated = active & (position == 3)
    truncated = active & ~terminated & (elapsed >= horizon)
    # Combine or mask array elements to form `reward`.
    reward = jnp.where(active, jnp.where(terminated, 1., -.01), 0.)
    return State(position, elapsed, state.done | terminated | truncated), reward, terminated, truncated

# Step 2 — Collect a batch and compute targets: scan emits time-major arrays; vmap keeps environments independent...
def log_probability(theta, observations, actions):
    logits = theta[jnp.minimum(observations, 2)]
    return jnp.where(actions == 1, jax.nn.log_sigmoid(logits), jax.nn.log_sigmoid(-logits))


# Define and JIT-compile `rollout(theta, key, batch_size, horizon)` so XLA traces and fuses the operations:
@partial(jax.jit, static_argnames=('batch_size', 'horizon'))
def rollout(theta, key, batch_size=256, horizon=8):
    # Create or split explicit PRNG key(s) (`(reset_key, action_key)`) for reproducible randomness.
    reset_key, action_key = jax.random.split(key)
    # Create or split explicit PRNG key(s) (`states`) for reproducible randomness.
    states = jax.vmap(reset)(jax.random.split(reset_key, batch_size))
    # Create or split explicit PRNG key(s) (`time_keys`) for reproducible randomness.
    time_keys = jax.random.split(action_key, horizon)
    def body(states, time_key):
        observations = states.position
        # Split the PRNG key deterministically into independent subkeys (`keys`).
        keys = jax.random.split(time_key, batch_size)
        probabilities = jax.nn.sigmoid(theta[jnp.minimum(observations, 2)])
        # Draw pseudorandom samples for `actions` using the explicit RNG state.
        actions = jax.vmap(jax.random.bernoulli)(keys, probabilities).astype(jnp.int32)
        # Vectorize across the batch dimension without a Python loop (`(next_states, rewards, terminated, truncated)`).
        next_states, rewards, terminated, truncated = jax.vmap(
            lambda s, a: step(s, a, horizon))(states, actions)
        record = dict(observation=observations, action=actions, reward=rewards,
                      active=~states.done, terminated=terminated, truncated=truncated,
                      old_logp=log_probability(theta, observations, actions))
        return next_states, record
    # Run a compiled sequential scan over the time/step axis (`(final, records)`).
    final, records = jax.lax.scan(body, states, time_keys)
    return final, records


def returns_to_go(rewards):
    """Undiscounted finite-episode objective; rewards after done are already zero."""
    return jnp.cumsum(rewards[::-1], axis=0)[::-1]

# Step 3 — Check shapes and episode boundaries: Exactly one ending event and zero padded rewards are stronger...
theta = jnp.zeros(3)
# Create or split explicit PRNG key(s) (`(final, records)`) for reproducible randomness.
final, records = rollout(theta, jax.random.key(5), batch_size=64, horizon=8)
# Check tensor shape invariant: `records['reward'].shape == (8`
assert records['reward'].shape == (8, 64)
assert bool(final.done.all())
assert bool(jnp.all(jnp.sum(records['terminated'] | records['truncated'], axis=0) == 1))
assert bool(jnp.all(jnp.where(records['active'], 0., records['reward']) == 0.))
# Reduce along axis=0 to compute `episode_returns`.
episode_returns = records['reward'].sum(axis=0)
print('return mean:', float(episode_returns.mean()))
print('active environments by transition:', records['active'].sum(axis=1))
Expected result: The trajectory has the stated time and environment axes, exactly one ending event per episode, and zero reward on every padded row.
Recorded reference execution
Reference output captured from executing the complete lesson script (code/main.py) and its assertions in the course CPU environment.
return mean: 0.5848437547683716
active environments by transition: [64 64 58 53 47 44 39 29]
return mean: 0.5848437547683716
active environments by transition: [64 64 58 53 47 44 39 29]
reward-to-go: [0.98 0.99 1.   0.  ]
PASS: rl-02
Download execution record · The notebook includes executed cells and figure outputs. Compare your run with these values; timings depend on the machine.
Replay the entire collector
# Experiment — Replay the entire collector: The random stream is part of the experiment state.
# Create or split explicit PRNG key(s) (`again`) for reproducible randomness.
again = rollout(theta, jax.random.key(5), 64, 8)[1]
for name in records:
    assert jnp.array_equal(records[name], again[name])
# Create or split explicit PRNG key(s) (`changed`) for reproducible randomness.
changed = rollout(theta, jax.random.key(6), 64, 8)[1]
assert not jnp.array_equal(records['action'], changed['action'])
Expected: Every field replays for the same configuration and key; another key changes actions.
The random stream is part of the experiment state. Replay in this environment is not a promise of identical outputs across arbitrary library versions or devices.
Reward-to-go by hand
# Experiment — Reward-to-go by hand: Zero padded rewards preserve the finite-episode sum, while the...
r = jnp.array([[-.01],[-.01],[1.],[0.]])
g = returns_to_go(r)
assert jnp.allclose(g[:,0], jnp.array([.98,.99,1.,0.]))
print('reward-to-go:', g[:,0])
Expected: The targets are .
Zero padded rewards preserve the finite-episode sum, while the active mask removes meaningless log probabilities.
Make it yours
Where to put your code: Append your solution at the bottom of phases/12-rl/02-batch-environments-and-scan-rollouts/code/main.py (or inside the Make it yours cell of exercises/rl-02.ipynb) and run python3 phases/12-rl/02-batch-environments-and-scan-rollouts/code/main.py to verify your prediction before opening the reference solution.
Change the batch to environments and the horizon to . Verify array shapes, one ending event per episode and zero rewards after finishing.
Show a writing guide and starter scaffold
How to write this exercise code: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
jnp.zeros / jnp.ones(shape, dtype=...)— Allocates a tensor of the givenshapeinitialized with constants.x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jax.random.PRNGKey(seed) & jax.random.split(key)— Manages explicit, stateless PRNG keys—always split a key before passing subkeys into independent random draws.
2. Step-by-step implementation plan:
- Create or split explicit PRNG key(s) (
(final7, r7)) for reproducible randomness. - Check tensor shape invariant:
r7['reward'].shape == (5
# Exercise solution: Change the batch to 7 environments and the horizon to 5.
# Create or split explicit PRNG key(s) (`(final7, r7)`) for reproducible randomness.
final7, r7 = rollout(...)  # TODO: compute final7, r7
# Check tensor shape invariant: `r7['reward'].shape == (5`
assert r7['reward'].shape  # TODO: complete assertion check
assert bool(final7.done.all())  # TODO: complete assertion check
assert jnp.array_equal((r7['terminated'] | r7['truncated']).sum(0), jnp.ones(7))  # TODO: complete assertion check
assert bool(jnp.all(jnp.where(r7['active'],0.,r7['reward'])  # TODO: complete assertion check
Reveal the reference solution
# Exercise solution: Change the batch to 7 environments and the horizon to 5.
# Create or split explicit PRNG key(s) (`(final7, r7)`) for reproducible randomness.
final7, r7 = rollout(theta, jax.random.key(17), 7, 5)
# Check tensor shape invariant: `r7['reward'].shape == (5`
assert r7['reward'].shape == (5,7)
assert bool(final7.done.all())
assert jnp.array_equal((r7['terminated'] | r7['truncated']).sum(0), jnp.ones(7))
assert bool(jnp.all(jnp.where(r7['active'],0.,r7['reward']) == 0.))
Catch a shifted mask
Transfer / diagnosis
Construct a two-action success from position . Compare masking by the pre-transition done flag with masking by the post-transition done flag.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
mask(...)— Callmaskwith your updated parameters or inputs from this lesson's workspace.State(...)— CallStatewith your updated parameters or inputs from this lesson's workspace.assert condition— Verify that the observed output shape, status, or numerical value satisfies the contract.
2. Step-by-step implementation plan:
- Accumulate the next contribution into
correct. - Accumulate the next contribution into
broken.
# Catch a shifted mask (Transfer / diagnosis): The broken mask removes the action responsible for success,...
s = State(...)  # TODO: compute s
correct, broken = ...  # TODO: compute correct, broken
for a in [1,1]:
    active = ...  # TODO: compute active
    s, reward, _, _ = step(...)  # TODO: compute s, reward, _, _
    # Accumulate the next contribution into `correct`.
    correct += float(reward*active)
    # Accumulate the next contribution into `broken`.
    broken += float(reward*(~s.done))
assert abs(correct-.99)  # TODO: complete assertion check
assert abs(broken+.01)  # TODO: complete assertion check
Show a hint
Record the mask before calling step; the successful transition still belongs to the episode.
Reveal reference solution and reasoning
# Catch a shifted mask (Transfer / diagnosis): The broken mask removes the action responsible for success,...
s = State(jnp.int32(1),jnp.int32(0),jnp.bool_(False))
correct, broken = 0., 0.
for a in [1,1]:
    active = ~s.done
    s, reward, _, _ = step(s,jnp.int32(a))
    # Accumulate the next contribution into `correct`.
    correct += float(reward*active)
    # Accumulate the next contribution into `broken`.
    broken += float(reward*(~s.done))
assert abs(correct-.99) < 1e-6
assert abs(broken+.01) < 1e-6
The broken mask removes the action responsible for success, leaving only a cost.
Check a deterministic policy limit
Transfer / diagnosis
Use very large positive logits and verify that every episode follows a shortest route.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
jnp.zeros / jnp.ones(shape, dtype=...)— Allocates a tensor of the givenshapeinitialized with constants.x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.jax.random.PRNGKey(seed) & jax.random.split(key)— Manages explicit, stateless PRNG keys—always split a key before passing subkeys into independent random draws.
2. Step-by-step implementation plan:
- Create or split explicit PRNG key(s) (
(_, easy)) for reproducible randomness. - Combine or mask array elements to form
expected.
# Check a deterministic policy limit (Transfer / diagnosis): The expected return is calculated from the initial position...
# Create or split explicit PRNG key(s) (`(_, easy)`) for reproducible randomness.
_, easy = rollout(...)  # TODO: compute _, easy
# Combine or mask array elements to form `expected`.
expected = jnp.where(...)  # TODO: compute expected
assert jnp.allclose(easy['reward'].sum(0),expected,atol=1e-6)  # TODO: complete assertion check
assert jnp.array_equal(easy['active'].sum(0),3-easy['observation'][0])  # TODO: complete assertion check
Show a hint
The two start states need different numbers of actions. Compare each return against its own initial position.
Reveal reference solution and reasoning
# Check a deterministic policy limit (Transfer / diagnosis): The expected return is calculated from the initial position...
# Create or split explicit PRNG key(s) (`(_, easy)`) for reproducible randomness.
_, easy = rollout(jnp.full(3,100.),jax.random.key(42),23,8)
# Combine or mask array elements to form `expected`.
expected = jnp.where(easy['observation'][0] == 0,.98,.99)
assert jnp.allclose(easy['reward'].sum(0),expected,atol=1e-6)
assert jnp.array_equal(easy['active'].sum(0),3-easy['observation'][0])
The expected return is calculated from the initial position rather than copied from the collector.
Diagnose the result
If reported return changes merely by padding an already finished trajectory, inspect reward masking. If success disappears from the objective, check whether active was recorded before step. If trajectories match too often, inspect broadcast or reused keys before increasing the batch.
Carry forward
- vmap handles independent environments; scan handles the dependent time sequence.
- Store behavior log probabilities and live-transition masks with rewards.
Keep your evidence
Keep reconstructed trajectories, randomized keys, padding masks and independent return calculations. Show how a changed key affects interaction without changing the environment rules.
Save your modified code, its output, and an explanation of your prediction. Checkpoint answers and exercise evidence are tracked separately.
Saved in this browser. Export or back up your portfolio anytime in My learning.
Verified on local CPU. Stage to a Cloud TPU VM via Cloud TPU setup to record accelerator execution receipts (TODO: add automated Cloud TPU CI execution receipts).