 JAX Pathways
Phase 02 / JAX transformations
Losses and value_and_grad
Revision v0.7.0 · Updated since your last visit. Review the changes; your progress is saved.
Lesson · about 55 minutes · CPU practice
Derive and audit a scalar loss, its parameter gradient, and stable versus unstable updates.
Phase study guide: preparation, milestones and project evidence
Before you start
Before this: Your first gradient
Hardware: CPU
Setup help: Python, notebook, or Cloud TPU VM
Use the tested CPU packages (the recorded environment uses Python 3.14.3). Other Python versions and accelerator environments require separate checks. The optional Cloud TPU specialization explains the target-specific execution boundaries. Logical CPU devices practice partitioning; they do not simulate TPU performance.
Download the repository ZIP or use your existing checkout. Extract it and open a terminal in the folder containing requirements-cpu.txt. The beginner ZIP is separate; these lessons use the full repository folder.
python3 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements-cpu.txtpy -3 -m venv .venv
.\.venv\Scripts\python.exe -m pip install -r requirements-cpu.txtAfter activation, run the complete worked example from that same folder:
python phases/02-transforms/02-losses-and-value-and-grad/code/main.py.\.venv\Scripts\python.exe phases/02-transforms/02-losses-and-value-and-grad/code/main.pyFor an incremental build, create main.py in your own practice folder, append each build block in order, and run python main.py with this environment active. Keep that file separate from the downloaded reference solution.
Download this lesson’s notebook. Open it with a Python kernel using the course environment. Run cells from the top after restarting the kernel; experiments depend on earlier definitions.
For local Jupyter, first install the course requirements using the Local Python steps, then use your environment’s Python to start Jupyter:
python -m pip install jupyterlab
python -m jupyter lab.\.venv\Scripts\python.exe -m pip install jupyterlab
.\.venv\Scripts\python.exe -m jupyter labSelect the downloaded transforms-02.ipynb file in JupyterLab. The notebook contains reference solutions; make your prediction and attempt each practice task before opening them. Restart the kernel before changing logical device setup.
The worked reference for this lesson is CPU-validated. Some references explicitly configure logical CPU devices; setting JAX_PLATFORMS does not adapt them to a TPU. Follow the execution matrix and reviewed multi-host example before attempting a target run.
For accelerator preparation, study TPU setup, observed runtime receipts, checkpointed jobs and precision and retained traces. These target paths remain unqualified on physical TPU hardware until an actual receipt is recorded. Cloud provisioning is optional for CPU learning.
Check: Loss ≈ ; gradient ≈ . Small floating-point differences are normal.
Revisit the guided CPU setup · Open 19: TPU Setup. Package instructions are CPU instructions; Windows and accelerator environments need their own validation.
What you will be able to do
- Derive a batch mean-squared-error gradient for one weight.
- Use value_and_grad to return a loss and its parameter gradient together.
- Predict how sum versus mean and residual scaling change an update.
- Verify an update with independent arithmetic and diagnose an unstable step.
The problem
Let’s turn the slope idea into a learning problem. We have three measurements and a model with one weight. How should that weight change to make its predictions better? We’ll calculate the prediction errors, combine them into one loss, and check the gradient by hand before asking JAX for the same result.
The idea
A loss value tells us how the current prediction is scored. Its derivative tells us how a small parameter change affects that score locally. value_and_grad returns both so we can inspect progress and choose an update without confusing the two quantities.
Read the value and derivative at the same point
Take as a new hand-worked objective. At , the loss is and the derivative is . A small positive change in the weight should decrease the loss. At , the derivative is zero but the loss remains .
The added constant changes every loss value but leaves the derivative unchanged. This is a useful diagnostic: if a derivative implementation changes when you add a parameter-independent constant, investigate the implementation. Equally, a nonzero minimum loss need not mean optimization failed.
When reading a plot of value and slope, compare them at the same horizontal coordinate and respect their different vertical units. The loss is not a gradient norm, and a small loss is separate from that all parameters are close to their intended values.
From three residuals to one decision
Read the formula from the inside out. For example , the model predicts . Subtract the observed target to get the residual, square it, and then average over all examples. The symbol just tells us to add the individual terms.
For inputs , targets and weight , the predictions are . The residuals are . Their squares add to , so the mean loss is . At weight , every residual is zero. These two settings give us independent checks before we use gradients.
Derive the gradient independently
Each squared residual contributes two factors when we differentiate: twice the residual, and the input from differentiating . We average those contributions just as we averaged the losses.
For this dataset, the loss simplifies to . At , its derivative is . The negative sign tells us that a small increase in the weight reduces the loss. That sign is useful: subtracting a negative gradient should move the weight upward, toward .
Read value_and_grad as an interface
The transformation returns a callable whose result is a pair: (value, gradient). In this lesson the value has shape and the gradient also has shape because the parameter is scalar. For a vector parameter, the gradient would have the vector parameter shape, not the batch shape. For a structured parameter tree, the gradient mirrors the tree.
Only the first positional argument is differentiated by default. Data can be explicit additional inputs without becoming parameters. Making that boundary explicit will matter when we compile training steps and reuse them across batches. value_and_grad bundles value and derivative computation in one transformed call; it does not guarantee a specific speedup for every workload.
Predict whether a step improves the objective
A gradient descent step uses . With and , w_new is about , much closer to than the initial . The loss therefore falls to about .
For this quadratic, the error evolves as . The loss decreases for a nonzero error when the absolute value of that multiplier is below one, giving . At , the multiplier is : the update crosses the optimum and increases the magnitude of the error. This threshold belongs to this dataset and objective, not to all training problems. Here is the step size, is the gradient, and measures how far the current weight is from . Try reading the error multiplier before running each step-size experiment.
Separate objective value from useful metrics
A single mean can hide an important individual error. Keep residuals or another diagnostic metric alongside the scalar loss. With has_aux=True, the function returns (scalar_loss, auxiliary_data), and value_and_grad returns ((loss, auxiliary_data), gradient). The differentiation objective is still the scalar loss; the auxiliary return does not create an additional objective.
In a larger model, auxiliary data might contain predictions or accuracy. This interface avoids confusing model outputs, logging information, and the objective. It also makes it easier to test what the step actually optimizes.
Loss and slope answer different questions
Predict before looking: Where is the loss smallest, and where does its slope change sign?
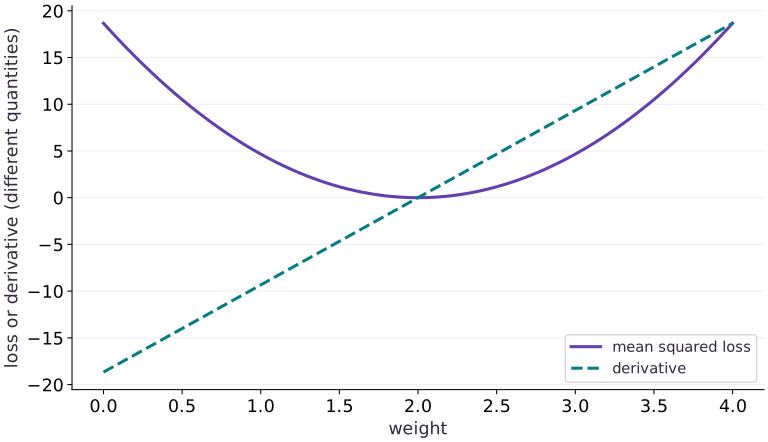
Read the figure
The solid bowl is mean squared loss and the dashed line is its derivative with respect to the weight. The horizontal axis varies the weight. The two vertical quantities have different meanings even though they share one axis.
Both reach zero at . At , the loss is about , while the derivative is about . Left of the minimum, the derivative is negative; right of it, the derivative is positive.
Connect it to the computation
The loss tells us how wrong the predictions are. The derivative tells us how that loss changes when the weight increases slightly. A negative derivative means moving right initially lowers the loss, which is why subtracting the gradient moves the weight toward .
The dashed line below zero is a negative slope, not a negative squared loss. Likewise, an intersection of the two curves away from the minimum has no special optimization meaning. value_and_grad returns these two different pieces of information together.
Open full-size figureDownload data and provenance
The notebook contains the data experiment, plotting code, and recorded figure output. Rerun it to test your changes.
Where to put & run this code: Work in phases/02-transforms/02-losses-and-value-and-grad/code/main.py (or downloaded exercises/transforms-02.py / exercises/transforms-02.ipynb) and execute from the repository root with python3 phases/02-transforms/02-losses-and-value-and-grad/code/main.py.
1 Step 1: Set up imports and input tensors
Import the required JAX modules and define the initial inputs for losses and value_and_grad.
import jax
import jax.numpy as jnp
Establishing explicit input shapes and dtypes first makes the downstream transformation contract deterministic.
2 Step 2: Apply the core JAX transformation
Write the core computation and transformation step over the initialized inputs.
x = jnp.array([1., 2., 3.])
y = 2. * x
def loss(weight):
    return jnp.mean((weight * x - y) ** 2)
Code building blocks in this step
jnp.array(values, dtype=...)— Constructs an immutable device-backed JAX array from Python/NumPy values.x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).
This stage executes the primary numerical transformation and binds the intermediate outputs.
3 Step 3: Verify shapes and numerical invariants
Check that the resulting arrays satisfy the expected shape, dtype, and numerical tolerances.
value, gradient = jax.value_and_grad(loss)(1.0)
assert jnp.allclose(value, 14./3.)
assert jnp.allclose(gradient, -28./3.)
Code building blocks in this step
jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.jax.value_and_grad(loss_fn)(params, ...)— Evaluates both the scalar loss and its gradient PyTree(loss_val, grads)in a single forward+backward pass.
These assertions lock in the exact numerical contract before you run the full experiment and variations.
View the cumulative build in main.py
These blocks append in order to the same file.
import jax
import jax.numpy as jnp

x = jnp.array([1., 2., 3.])
y = 2. * x
def loss(weight):
    return jnp.mean((weight * x - y) ** 2)

value, gradient = jax.value_and_grad(loss)(1.0)
assert jnp.allclose(value, 14./3.)
assert jnp.allclose(gradient, -28./3.)
Run the example
python3 phases/02-transforms/02-losses-and-value-and-grad/code/main.pyAbout this command
This shortcut uses an activated macOS/Linux course environment in the repository folder. For Windows, use the explicit interpreter command in “Setup help” above. The script includes worked examples and reference solutions.
Inspect the complete assembled example
# Losses and value_and_grad: A loss value tells us how the current prediction is scored.
import jax
import jax.numpy as jnp
x = jnp.array([1., 2., 3.])
y = 2. * x
def loss(weight):
    return jnp.mean((weight * x - y) ** 2)
# Differentiate the objective to obtain `(value, gradient)` via automatic differentiation.
value, gradient = jax.value_and_grad(loss)(1.0)
print("Loss:", float(value), "gradient:", float(gradient))
assert jnp.allclose(value, 14./3.)
assert jnp.allclose(gradient, -28./3.)
Expected result: Loss ≈ ; gradient ≈ . Small floating-point differences are normal.
Recorded reference execution
Reference output captured from executing the complete lesson script (code/main.py) and its assertions in the course CPU environment.
Loss: 4.6666669845581055 gradient: -9.333333969116211
weight / loss / gradient: 0.0 18.666667938232422 -18.666667938232422
weight / loss / gradient: 1.0 4.6666669845581055 -9.333333969116211
weight / loss / gradient: 2.0 0.0 0.0
PASS: transforms-02
Download execution record · The notebook includes executed cells and figure outputs. Compare your run with these values; timings depend on the machine.
Check JAX against the handwritten gradient
# Experiment — Check JAX against the handwritten gradient: A derivative describes the direction.
def analytic_loss_gradient(weight):
    return 2. * jnp.mean((weight * x - y) * x)
for weight in (0., 1., 2.):
    # Differentiate the objective to obtain `(value_here, grad_here)` via automatic differentiation.
    value_here, grad_here = jax.value_and_grad(loss)(weight)
    print("weight / loss / gradient:", weight, float(value_here), float(grad_here))
    assert jnp.allclose(grad_here, analytic_loss_gradient(weight))
Expected: The gradients are , , and ; the losses are , , and .
A derivative describes the direction. A new objective value is obtained only after a chosen update and a new evaluation.
Return residuals without changing the objective
# Experiment — Return residuals without changing the objective: The return structure separates logging data from a scalar...
def loss_with_residuals(weight):
    residuals = weight * x - y
    return jnp.mean(residuals ** 2), residuals
# Differentiate the objective to obtain `((aux_value, residuals), aux_grad...` via automatic differentiation.
(aux_value, residuals), aux_gradient = jax.value_and_grad(loss_with_residuals, has_aux=True)(1.)
# Check tensor shape invariant: `residuals.shape == (3,)`
assert residuals.shape == (3,)
assert jnp.allclose(residuals, jnp.array([-1., -2., -3.]))
assert jnp.allclose(aux_value, value)
assert jnp.allclose(aux_gradient, gradient)
Expected: The objective and gradient match the original; residuals are a separate array of shape .
The return structure separates logging data from a scalar optimization target. Reducing or selecting the wrong return value is a common source of interface bugs.
Make it yours
Where to put your code: Append your solution at the bottom of phases/02-transforms/02-losses-and-value-and-grad/code/main.py (or inside the Make it yours cell of exercises/transforms-02.ipynb) and run python3 phases/02-transforms/02-losses-and-value-and-grad/code/main.py to verify your prediction before opening the reference solution.
Foundation · Starting from , calculate the next weight and loss for and . Verify both. Explain the overshoot using the error multiplier rather than concluding that autodiff is wrong.
Show a writing guide and starter scaffold
How to write this exercise code: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.
2. Step-by-step implementation plan:
- Set up the changed input or configuration parameters requested in the prompt.
- Run the target function or transformation and assert that the output matches your prediction.
# Exercise solution: Foundation · Starting from w=1, calculate the next weight and loss for...
small_step = ...  # TODO: compute small_step
large_step = ...  # TODO: compute large_step
assert jnp.allclose(small_step, 29. / 15.)  # TODO: complete assertion check
assert loss(small_step)  # TODO: complete assertion check
assert loss(large_step)  # TODO: complete assertion check
assert jnp.allclose(loss(2.), 0.)  # TODO: complete assertion check
Reveal the reference solution
# Exercise solution: Foundation · Starting from w=1, calculate the next weight and loss for...
small_step = 1. - 0.1 * gradient
large_step = 1. - 0.3 * gradient
assert jnp.allclose(small_step, 29. / 15.)
assert loss(small_step) < value
assert loss(large_step) > value
assert jnp.allclose(loss(2.), 0.)
Make the data boundary explicit
Practice
Rewrite loss(weight, inputs, targets) with data as arguments. Use value_and_grad and verify the gradient at against the hand-derived result.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.jax.value_and_grad(loss_fn)(params, ...)— Evaluates both the scalar loss and its gradient PyTree(loss_val, grads)in a single forward+backward pass.
2. Step-by-step implementation plan:
- Differentiate the objective to obtain
(v_explicit, g_explicit)via automatic differentiation.
# Make the data boundary explicit (Practice): Keeping data explicit prepares the function for new batches...
def explicit_loss(weight, inputs, targets):
    return ...  # TODO: return computed result
# Differentiate the objective to obtain `(v_explicit, g_explicit)` via automatic differentiation.
v_explicit, g_explicit = jax.value_and_grad(...)  # TODO: compute v_explicit, g_explicit
assert jnp.allclose(v_explicit, 14. / 3.)  # TODO: complete assertion check
assert jnp.allclose(g_explicit, -28. / 3.)  # TODO: complete assertion check
Show a hint
Default differentiation is with respect to the first argument, not every floating-point input.
Reveal reference solution and reasoning
# Make the data boundary explicit (Practice): Keeping data explicit prepares the function for new batches...
def explicit_loss(weight, inputs, targets):
    return jnp.mean((weight * inputs - targets) ** 2)
# Differentiate the objective to obtain `(v_explicit, g_explicit)` via automatic differentiation.
v_explicit, g_explicit = jax.value_and_grad(explicit_loss)(1., x, y)
assert jnp.allclose(v_explicit, 14. / 3.)
assert jnp.allclose(g_explicit, -28. / 3.)
Keeping data explicit prepares the function for new batches and avoids accidentally closing over stale training data.
Audit reduction and batch replication
Challenge
Compare the mean and sum loss gradients. Repeat this batch twice and predict the gradient under both reductions. Explain which learning-rate adjustment makes a sum-based update match a mean-based update.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.jax.grad(loss_fn)(params, ...)— Transforms a scalar-output function into a function returning the gradient PyTree with the same structure asparams.
2. Step-by-step implementation plan:
- Differentiate the objective to obtain
g_meanvia automatic differentiation. - Differentiate the objective to obtain
g_sumvia automatic differentiation.
# Audit reduction and batch replication (Challenge): Mean gradients stay fixed under exact batch replication; sum...
def summed_loss(weight, inputs, targets):
    return ...  # TODO: return computed result
# Differentiate the objective to obtain `g_mean` via automatic differentiation.
g_mean = jax.grad(...)  # TODO: compute g_mean
# Differentiate the objective to obtain `g_sum` via automatic differentiation.
g_sum = jax.grad(...)  # TODO: compute g_sum
x_twice, y_twice = jnp.tile(...)  # TODO: compute x_twice, y_twice
assert jnp.allclose(g_sum, len(x) * g_mean)  # TODO: complete assertion check
assert jnp.allclose(jax.grad(explicit_loss)(1., x_twice, y_twice), g_mean)  # TODO: complete assertion check
assert jnp.allclose(jax.grad(summed_loss)(1., x_twice, y_twice), 2. * g_sum)  # TODO: complete assertion check
assert jnp.allclose(1. - 0.1 * g_mean, 1. - (0.1 / len(x)) * g_sum)  # TODO: complete assertion check
Show a hint
Duplicate data are not new information. Track the factor in the mathematical objective.
Reveal reference solution and reasoning
# Audit reduction and batch replication (Challenge): Mean gradients stay fixed under exact batch replication; sum...
def summed_loss(weight, inputs, targets):
    return jnp.sum((weight * inputs - targets) ** 2)
# Differentiate the objective to obtain `g_mean` via automatic differentiation.
g_mean = jax.grad(explicit_loss)(1., x, y)
# Differentiate the objective to obtain `g_sum` via automatic differentiation.
g_sum = jax.grad(summed_loss)(1., x, y)
x_twice, y_twice = jnp.tile(x, 2), jnp.tile(y, 2)
assert jnp.allclose(g_sum, len(x) * g_mean)
assert jnp.allclose(jax.grad(explicit_loss)(1., x_twice, y_twice), g_mean)
assert jnp.allclose(jax.grad(summed_loss)(1., x_twice, y_twice), 2. * g_sum)
assert jnp.allclose(1. - 0.1 * g_mean, 1. - (0.1 / len(x)) * g_sum)
Mean gradients stay fixed under exact batch replication; sum gradients scale with the count. Compensating the rate by 1/N makes this particular SGD update match.
Diagnose the result
If an update increases loss, verify the subtraction sign, reduction scale, and learning rate before blaming the gradient transform. If the objective is nonscalar, inspect the residual and reduction shapes. If metrics look plausible but gradients are wrong, compare against the independently derived formula at more than one parameter setting. These checks separate implementation mistakes from an unstable optimization choice.
Carry forward
- A scalar reduction defines both the objective and the update scale.
- value_and_grad returns a value/gradient pair; the gradient follows the parameter shape.
- Independent arithmetic and multiple parameter settings provide a useful numerical check.
- Descent direction does not guarantee descent with an arbitrary step size.
Keep your evidence
Keep handwritten loss/gradient arithmetic, checks at three weights, small/large-rate update results, auxiliary residuals, and mean-versus-sum batch-replication results. Explain the update-scale change.
Save your modified code, its output, and an explanation of your prediction. Checkpoint answers and exercise evidence are tracked separately.
Saved in this browser. Export or back up your portfolio anytime in My learning.
Verified on local CPU. Stage to a Cloud TPU VM via Cloud TPU setup to record accelerator execution receipts (TODO: add automated Cloud TPU CI execution receipts).