 JAX Pathways
Phase 11 / Probabilistic modeling
Variational inference and model checking
Revision v0.7.0 · Updated since your last visit. Review the changes; your progress is saved.
Lesson · about 125 minutes · CPU practice
Derive the diagonal Gaussian variational optimum for a correlated target Separate optimization error from variational-family error
Phase study guide: preparation, milestones and project evidence
Before you start
Before this: Hamiltonian Monte Carlo and sampler diagnostics
Hardware: CPU
Setup help: Python, notebook, or Cloud TPU VM
Use the tested CPU packages (the recorded environment uses Python 3.14.3). Other Python versions and accelerator environments require separate checks. The optional Cloud TPU specialization explains the target-specific execution boundaries. Logical CPU devices practice partitioning; they do not simulate TPU performance.
Download the repository ZIP or use your existing checkout. Extract it and open a terminal in the folder containing requirements-cpu.txt. The beginner ZIP is separate; these lessons use the full repository folder.
python3 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements-cpu.txtpy -3 -m venv .venv
.\.venv\Scripts\python.exe -m pip install -r requirements-cpu.txtAfter activation, run the complete worked example from that same folder:
python phases/11-probability/04-variational-inference-and-model-checking/code/main.py.\.venv\Scripts\python.exe phases/11-probability/04-variational-inference-and-model-checking/code/main.pyFor an incremental build, create main.py in your own practice folder, append each build block in order, and run python main.py with this environment active. Keep that file separate from the downloaded reference solution.
Download this lesson’s notebook. Open it with a Python kernel using the course environment. Run cells from the top after restarting the kernel; experiments depend on earlier definitions.
For local Jupyter, first install the course requirements using the Local Python steps, then use your environment’s Python to start Jupyter:
python -m pip install jupyterlab
python -m jupyter lab.\.venv\Scripts\python.exe -m pip install jupyterlab
.\.venv\Scripts\python.exe -m jupyter labSelect the downloaded probability-04.ipynb file in JupyterLab. The notebook contains reference solutions; make your prediction and attempt each practice task before opening them. Restart the kernel before changing logical device setup.
The worked reference for this lesson is CPU-validated. Some references explicitly configure logical CPU devices; setting JAX_PLATFORMS does not adapt them to a TPU. Follow the execution matrix and reviewed multi-host example before attempting a target run.
For accelerator preparation, study TPU setup, observed runtime receipts, checkpointed jobs and precision and retained traces. These target paths remain unqualified on physical TPU hardware until an actual receipt is recorded. Cloud provisioning is optional for CPU learning.
Check: The optimized variances are , compared with target marginal variances . Remaining KL is approximately . The curved stress fixture has visibly structured residuals and low nominal interval coverage.
Revisit the guided CPU setup · Open 19: TPU Setup. Package instructions are CPU instructions; Windows and accelerator environments need their own validation.
What you will be able to do
- Derive the diagonal Gaussian variational optimum for a correlated target
- Separate optimization error from variational-family error
- Use reparameterization to inspect a Monte Carlo objective
- Diagnose mean-function mismatch using predictive residuals
The problem
A variational optimizer finishes with a stable objective, and its posterior mean agrees with a reference. Can its uncertainty still be wrong? We will optimize a diagonal Gaussian against a correlated exact target, then check a prediction under a deliberately misspecified observation model. These are two different failure sources: an inference approximation and a model assumption.
The idea
Variational inference fits a tractable approximation to a posterior. The approximation family limits what dependencies it can represent. A good mean estimate can coexist with a poor uncertainty estimate.
Missing covariance can hide uncertainty
Consider two variables, each with variance , and covariance . Their sum has variance . A diagonal approximation with the same marginal variances but zero covariance would give variance for the sum.
This isolates the effect of ignoring covariance; an actual fitted approximation can also change the marginal variances. Draw covariance ellipses from the real matrices rather than sketching arbitrary shapes.
The lesson's variance comparison asks which downstream quantities are sensitive to the approximation. Check projections such as sums and differences, not only coordinate means. A different approximation family or objective can behave differently, so avoid treating one fixture as a universal direction of error.
The covariance changes uncertainty in a sum
Predict: Can matching each coordinate's mean prove a correct distribution for their sum?
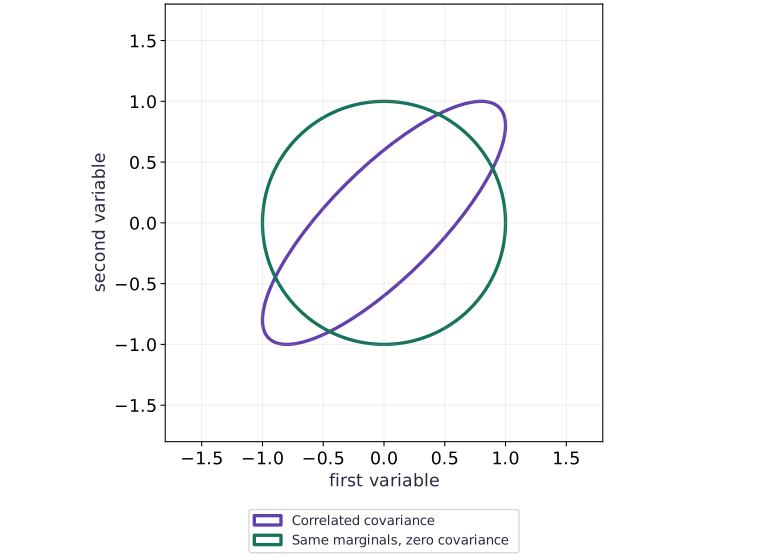
Both analytic matrices have unit marginal variances. Purple adds covariance , stretching along the shared diagonal; green has zero covariance. These are unit Mahalanobis-distance contours, not 95% regions or fitted samples. Sum variances are and , respectively.
Name the approximation and the KL direction
The target covariance has unit marginal variances and correlation . Our variational family has a location and diagonal covariance . It cannot tilt its uncertainty ellipse. The KL direction matters: minimizing penalizes placing probability where the target density is low. For this Gaussian target, optimizing over diagonal gives and , where . Those are conditional-variance quantities, not the target marginal variances.
Work through the remaining error
For correlation , the covariance determinant is , and each diagonal precision is . The optimal diagonal variance is therefore . Each standard deviation is , whereas the target marginal standard deviations are . The means can be right while uncertainty is too narrow. At this optimum the KL is about , not zero. More optimization cannot remove that family restriction.
Connect the exact objective to an ELBO
In a model with data and latent parameters , the ELBO is the expectation of under . The gap to log evidence is . Reparameterize a diagonal normal as , with standard-normal , to differentiate an estimated objective with respect to . Our exact objective avoids Monte Carlo noise so the family restriction is clear. The experiment below estimates the same KL with independent random draws and compares it to the analytic value.
Inspect what the model predicts, not only its optimizer
A posterior predictive check draws plausible replicated observations and compares meaningful features with the observed data. Choose a discrepancy such as residual curvature, outlier count or group-specific spread; a single global mean can conceal a failure. Our stress fixture uses a zero linear mean and noise standard deviation , then supplies targets . Positive residuals at both ends and negative residuals near the center reveal curvature missing from the mean model. Narrower intervals cannot repair that pattern.
Keep inference and model errors separate
The first experiment has a correct known target but an inadequate variational family. The second deliberately changes the data-generating mean while retaining an inadequate likelihood. Posterior predictive checks can reveal tension but are verified separately from model truth. For a real workflow, choose checks before inspecting a final held-out split, keep group sizes and uncertainty in reported coverage, and refit only on permitted data. TODO (NumPyro Extension): Compare this hand-written ELBO loop against numpyro.infer.SVI and numpyro.infer.NUTS on the same target density.
An accurate mean can coexist with underestimated uncertainty
Predict before looking: Will optimizing a diagonal approximation recover the full target marginal variances?
Read the figure
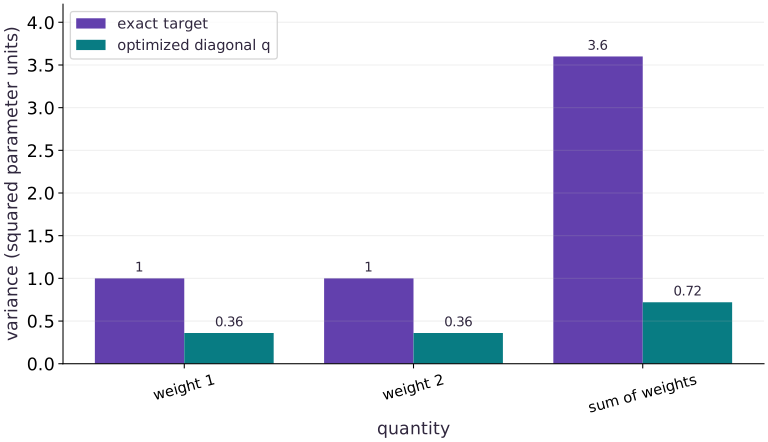
The horizontal categories identify three quantities: variance of the first weight, variance of the second weight and variance of their sum. The vertical axis is variance in squared parameter units. The target bars are . The optimized diagonal approximation gives . The especially large gap for the sum comes from both smaller marginal variances and missing positive covariance.
Connect it to the computation
The code checks that the optimizer reaches the analytic variational optimum. The remaining gap therefore comes from the chosen diagonal family and KL direction on this particular Gaussian target. It is not evidence that every variational approximation has the same bias; a full-covariance Gaussian can represent this target.
Open full-size figureDownload data and provenance
The notebook contains the data experiment, plotting code, and recorded figure output. Rerun it to test your changes.
Where to put & run this code: Work in phases/11-probability/04-variational-inference-and-model-checking/code/main.py (or downloaded exercises/probability-04.py / exercises/probability-04.ipynb) and execute from the repository root with python3 phases/11-probability/04-variational-inference-and-model-checking/code/main.py.
1 Specify a correlated target and a simpler approximation
Create a fresh main.py. Our target is an exactly known Gaussian so approximation error can be measured independently of optimization error.
# Step 1 — 1. Specify a correlated target and a simpler approximation: KL here means KL(q || p).
import numpy as np
import jax
import jax.numpy as jnp
mu=jnp.array([1.,-1.])
Sigma=jnp.array([[1.,.8],[.8,1.]])
P=jnp.linalg.solve(Sigma,jnp.eye(2))
def kl(params):
    location,log_scale=params
    variance=jnp.exp(2*log_scale)
    delta=location-mu
    return .5*(jnp.sum(jnp.diag(P)*variance)+delta@P@delta-2+jnp.linalg.slogdet(Sigma)[1]-jnp.sum(2*log_scale))
Code building blocks in this step
jnp.array(values, dtype=...)— Constructs an immutable device-backed JAX array from Python/NumPy values.jnp.zeros / jnp.ones(shape, dtype=...)— Allocates a tensor of the givenshapeinitialized with constants.x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).
KL here means KL(q || p). The full covariance of p is retained, while q has independent coordinates.
2 Optimize and compare to the exact variational optimum
Append a scan of gradient updates. The analytic optimum uses inverse diagonal precision, which differs from the target marginal variances.
# Step 2 — 2. Optimize and compare to the exact variational optimum: Optimization has found the best diagonal Gaussian in this KL...
# Define `update(params, _)` to evaluate the objective and its automatic derivatives:
def update(params,_):
    # Differentiate the objective to obtain `grads` via automatic differentiation.
    grads=jax.grad(kl)(params)
    # Transform every leaf of the parameter PyTree (`new`).
    new=jax.tree.map(lambda value,grad:value-.05*grad,params,grads)
    return new,kl(new)
# Run compiled structured control flow via `jax.lax` (`(params, history)`).
params,history=jax.lax.scan(update,(jnp.zeros(2),jnp.zeros(2)),None,length=600)
location,log_scale=params
variance=jnp.exp(2*log_scale)
assert jnp.allclose(location,mu,atol=1e-4)
assert jnp.allclose(variance,1/jnp.diag(P),atol=1e-5)
assert jnp.allclose(variance,jnp.array([.36,.36]),atol=1e-5)
assert kl(params)>0.4
print('VI mean:',location,'variances:',variance,'remaining KL:',float(kl(params)))
Code building blocks in this step
jnp.array(values, dtype=...)— Constructs an immutable device-backed JAX array from Python/NumPy values.jnp.zeros / jnp.ones(shape, dtype=...)— Allocates a tensor of the givenshapeinitialized with constants.jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.jax.grad(loss_fn)(params, ...)— Transforms a scalar-output function into a function returning the gradient PyTree with the same structure asparams.
Optimization has found the best diagonal Gaussian in this KL direction, yet it cannot reproduce target correlation.
3 Check a prediction under a changed data-generating process
Append an explicit model-mismatch experiment. The fitted line predicts zero, but new synthetic targets have curvature. Standardized residuals expose the missing structure.
# Step 3 — 3. Check a prediction under a changed data-generating process: This is a deterministic stress fixture with nine targets, not an...
x=jnp.linspace(-2,2,9)
linear_mean=jnp.zeros_like(x)
noise_scale=.25
curved_targets=x**2-1.
standardized_residual=(curved_targets-linear_mean)/noise_scale
# Aggregate array values to compute `coverage`.
coverage=jnp.mean(jnp.abs(standardized_residual)<=1.96)
assert coverage<.4
assert standardized_residual[0]>10
print('synthetic nominal-95% interval coverage:',float(coverage))
print('standardized residuals:',standardized_residual)
Code building blocks in this step
jnp.linspace(start, stop, num)— Createsnumevenly spaced float points across the closed interval[start, stop].x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).
This is a deterministic stress fixture with nine targets, not an estimate of population coverage. It isolates a mean-function mismatch that more posterior draws cannot repair.
View the cumulative build in main.py
These blocks append in order to the same file.
# Step 1 — 1. Specify a correlated target and a simpler approximation: KL here means KL(q || p).
import numpy as np
import jax
import jax.numpy as jnp
mu=jnp.array([1.,-1.])
Sigma=jnp.array([[1.,.8],[.8,1.]])
P=jnp.linalg.solve(Sigma,jnp.eye(2))
def kl(params):
    location,log_scale=params
    variance=jnp.exp(2*log_scale)
    delta=location-mu
    return .5*(jnp.sum(jnp.diag(P)*variance)+delta@P@delta-2+jnp.linalg.slogdet(Sigma)[1]-jnp.sum(2*log_scale))

# Step 2 — 2. Optimize and compare to the exact variational optimum: Optimization has found the best diagonal Gaussian in this KL...
# Define `update(params, _)` to evaluate the objective and its automatic derivatives:
def update(params,_):
    # Differentiate the objective to obtain `grads` via automatic differentiation.
    grads=jax.grad(kl)(params)
    # Transform every leaf of the parameter PyTree (`new`).
    new=jax.tree.map(lambda value,grad:value-.05*grad,params,grads)
    return new,kl(new)
# Run compiled structured control flow via `jax.lax` (`(params, history)`).
params,history=jax.lax.scan(update,(jnp.zeros(2),jnp.zeros(2)),None,length=600)
location,log_scale=params
variance=jnp.exp(2*log_scale)
assert jnp.allclose(location,mu,atol=1e-4)
assert jnp.allclose(variance,1/jnp.diag(P),atol=1e-5)
assert jnp.allclose(variance,jnp.array([.36,.36]),atol=1e-5)
assert kl(params)>0.4
print('VI mean:',location,'variances:',variance,'remaining KL:',float(kl(params)))

# Step 3 — 3. Check a prediction under a changed data-generating process: This is a deterministic stress fixture with nine targets, not an...
x=jnp.linspace(-2,2,9)
linear_mean=jnp.zeros_like(x)
noise_scale=.25
curved_targets=x**2-1.
standardized_residual=(curved_targets-linear_mean)/noise_scale
# Aggregate array values to compute `coverage`.
coverage=jnp.mean(jnp.abs(standardized_residual)<=1.96)
assert coverage<.4
assert standardized_residual[0]>10
print('synthetic nominal-95% interval coverage:',float(coverage))
print('standardized residuals:',standardized_residual)
Run the example
python3 phases/11-probability/04-variational-inference-and-model-checking/code/main.pyAbout this command
This shortcut uses an activated macOS/Linux course environment in the repository folder. For Windows, use the explicit interpreter command in “Setup help” above. The script includes worked examples and reference solutions.
Inspect the complete assembled example
# Step 1 — 1. Specify a correlated target and a simpler approximation: KL here means KL(q || p).
import numpy as np
import jax
import jax.numpy as jnp
mu=jnp.array([1.,-1.])
Sigma=jnp.array([[1.,.8],[.8,1.]])
P=jnp.linalg.solve(Sigma,jnp.eye(2))
def kl(params):
    location,log_scale=params
    variance=jnp.exp(2*log_scale)
    delta=location-mu
    return .5*(jnp.sum(jnp.diag(P)*variance)+delta@P@delta-2+jnp.linalg.slogdet(Sigma)[1]-jnp.sum(2*log_scale))

# Step 2 — 2. Optimize and compare to the exact variational optimum: Optimization has found the best diagonal Gaussian in this KL...
# Define `update(params, _)` to evaluate the objective and its automatic derivatives:
def update(params,_):
    # Differentiate the objective to obtain `grads` via automatic differentiation.
    grads=jax.grad(kl)(params)
    # Transform every leaf of the parameter PyTree (`new`).
    new=jax.tree.map(lambda value,grad:value-.05*grad,params,grads)
    return new,kl(new)
# Run compiled structured control flow via `jax.lax` (`(params, history)`).
params,history=jax.lax.scan(update,(jnp.zeros(2),jnp.zeros(2)),None,length=600)
location,log_scale=params
variance=jnp.exp(2*log_scale)
assert jnp.allclose(location,mu,atol=1e-4)
assert jnp.allclose(variance,1/jnp.diag(P),atol=1e-5)
assert jnp.allclose(variance,jnp.array([.36,.36]),atol=1e-5)
assert kl(params)>0.4
print('VI mean:',location,'variances:',variance,'remaining KL:',float(kl(params)))

# Step 3 — 3. Check a prediction under a changed data-generating process: This is a deterministic stress fixture with nine targets, not an...
x=jnp.linspace(-2,2,9)
linear_mean=jnp.zeros_like(x)
noise_scale=.25
curved_targets=x**2-1.
standardized_residual=(curved_targets-linear_mean)/noise_scale
# Aggregate array values to compute `coverage`.
coverage=jnp.mean(jnp.abs(standardized_residual)<=1.96)
assert coverage<.4
assert standardized_residual[0]>10
print('synthetic nominal-95% interval coverage:',float(coverage))
print('standardized residuals:',standardized_residual)
Expected result: The optimized variances are , compared with target marginal variances . Remaining KL is approximately . The curved stress fixture has visibly structured residuals and low nominal interval coverage.
Recorded reference execution
Reference output captured from executing the complete lesson script (code/main.py) and its assertions in the course CPU environment.
VI mean: [ 0.99999994 -0.99999994] variances: [0.36000016 0.36000016] remaining KL: 0.5108256340026855
synthetic nominal-95% interval coverage: 0.2222222238779068
standardized residuals: [12.  5.  0. -3. -4. -3.  0.  5. 12.]
VI mean: [ 0.99999994 -0.99999994] variances: [0.36000016 0.36000016] remaining KL: 0.5108256340026855
synthetic nominal-95% interval coverage: 0.2222222238779068
standardized residuals: [12.  5.  0. -3. -4. -3.  0.  5. 12.]
Monte Carlo KL: 0.5119153261184692
model self-coverage: 0.9493999481201172
PASS: probability-04
Download execution record · The notebook includes executed cells and figure outputs. Compare your run with these values; timings depend on the machine.
Monte Carlo KL through reparameterization
# Experiment — Monte Carlo KL through reparameterization: Matching the exact KL validates this estimator on the fixture;...
# Create or split explicit PRNG key(s) (`eps`) for reproducible randomness.
eps=jax.random.normal(jax.random.key(52),(40000,2))
z=location+jnp.exp(log_scale)*eps
delta=z-mu
logp=-.5*(jnp.einsum('ni,ij,nj->n',delta,P,delta)+2*jnp.log(2*jnp.pi)+jnp.linalg.slogdet(Sigma)[1])
# Reduce along axis=1 to compute `logq`.
logq=-.5*jnp.sum(eps**2,axis=1)-jnp.sum(log_scale)-jnp.log(2*jnp.pi)
# Aggregate array values to compute `estimate`.
estimate=jnp.mean(logq-logp)
assert abs(float(estimate-kl(params)))<.03
print('Monte Carlo KL:',float(estimate))
Expected: The estimate is close to the exact nonzero KL of .
Matching the exact KL validates this estimator on the fixture; it does not imply the approximate posterior is exact.
Count model-generated intervals
# Experiment — Count model-generated intervals: Self-coverage checks interval arithmetic under the model.
# Create or split explicit PRNG key(s) (`replicated`) for reproducible randomness.
replicated=.25*jax.random.normal(jax.random.key(83),(40000,))
# Aggregate array values to compute `model_coverage`.
model_coverage=jnp.mean(jnp.abs(replicated)<=1.96*.25)
assert .94<model_coverage<.96
print("model self-coverage:",float(model_coverage))
Expected: Approximately lie inside their model interval.
Self-coverage checks interval arithmetic under the model. It is distinct from coverage under the curved alternative.
Make it yours
Where to put your code: Append your solution at the bottom of phases/11-probability/04-variational-inference-and-model-checking/code/main.py (or inside the Make it yours cell of exercises/probability-04.ipynb) and run python3 phases/11-probability/04-variational-inference-and-model-checking/code/main.py to verify your prediction before opening the reference solution.
Replace the target correlation by zero and rederive the optimal diagonal variances and minimum KL. Verify that the diagonal family can now represent the target exactly.
Show a writing guide and starter scaffold
How to write this exercise code: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
jnp.zeros / jnp.ones(shape, dtype=...)— Allocates a tensor of the givenshapeinitialized with constants.x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.
2. Step-by-step implementation plan:
- Set up the changed input or configuration parameters requested in the prompt.
- Run the target function or transformation and assert that the output matches your prediction.
# Exercise solution: Replace the target correlation by zero and rederive the optimal...
def independent_kl(location,log_scale):
    return ...  # TODO: return computed result
assert jnp.allclose(independent_kl(mu,jnp.zeros(2)),0.)  # TODO: complete assertion check
Reveal the reference solution
# Exercise solution: Replace the target correlation by zero and rederive the optimal...
def independent_kl(location,log_scale):
    return .5*(jnp.sum(jnp.exp(2*log_scale))+jnp.sum((location-mu)**2)-2-jnp.sum(2*log_scale))
assert jnp.allclose(independent_kl(mu,jnp.zeros(2)),0.)
A correct diagonal is not a correct covariance
Transfer / diagnosis
Compare the variance of the sum of two target coordinates with that under the optimized diagonal approximation.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
jnp.zeros / jnp.ones(shape, dtype=...)— Allocates a tensor of the givenshapeinitialized with constants.x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jnp.allclose(actual, expected, rtol=..., atol=...)— Checks that two arrays match elementwise within floating-point tolerance.
2. Step-by-step implementation plan:
- Perform matrix / vector contraction (
@) to computetrue_sum_var. - Aggregate array values to compute
approx_sum_var.
# A correct diagonal is not a correct covariance (Transfer / diagnosis): Joint predictions can reveal approximation error that...
direction = jnp.ones(...)  # TODO: compute direction
# Perform matrix / vector contraction (`@`) to compute `true_sum_var`.
true_sum_var = ...  # TODO: compute true_sum_var
# Aggregate array values to compute `approx_sum_var`.
approx_sum_var = jnp.sum(...)  # TODO: compute approx_sum_var
assert jnp.allclose(true_sum_var,3.6)  # TODO: complete assertion check
assert jnp.allclose(approx_sum_var,.72,atol=1e-5)  # TODO: complete assertion check
Show a hint
Retain the off-diagonal covariance terms in the target calculation.
Reveal reference solution and reasoning
# A correct diagonal is not a correct covariance (Transfer / diagnosis): Joint predictions can reveal approximation error that...
direction=jnp.ones(2)
# Perform matrix / vector contraction (`@`) to compute `true_sum_var`.
true_sum_var=direction@Sigma@direction
# Aggregate array values to compute `approx_sum_var`.
approx_sum_var=jnp.sum(variance)
assert jnp.allclose(true_sum_var,3.6)
assert jnp.allclose(approx_sum_var,.72,atol=1e-5)
Joint predictions can reveal approximation error that examining means alone completely misses.
Repair the changed mean without hiding noise
Transfer / diagnosis
Replace the zero mean by the known curved mean in the stress fixture. Draw fresh noisy targets and compare residual spread to the stated noise scale.
Show a writing guide and starter scaffold
How to write this practice solution: step-by-step recipe & starter scaffold
1. Key functions & syntax to use:
jnp.linspace(start, stop, num)— Createsnumevenly spaced float points across the closed interval[start, stop].x.sum(axis=...) / x.mean(axis=..., keepdims=...)— Reduces values along the namedaxis(the axis you name is collapsed unlesskeepdims=True).jax.random.PRNGKey(seed) & jax.random.split(key)— Manages explicit, stateless PRNG keys—always split a key before passing subkeys into independent random draws.
2. Step-by-step implementation plan:
- Create or split explicit PRNG key(s) (
fresh) for reproducible randomness.
# Repair the changed mean without hiding noise (Transfer / diagnosis): Correcting the mean removes systematic residual structure in...
truth = jnp.linspace(...)  # TODO: compute truth
# Create or split explicit PRNG key(s) (`fresh`) for reproducible randomness.
fresh = ...  # TODO: compute fresh
residual = ...  # TODO: compute residual
assert abs(float(residual.std())-.25)  # TODO: complete assertion check
assert abs(float(residual.mean()))  # TODO: complete assertion check
Show a hint
The fixture supplies the true curvature; real data would require fitting and held-out evaluation.
Reveal reference solution and reasoning
# Repair the changed mean without hiding noise (Transfer / diagnosis): Correcting the mean removes systematic residual structure in...
truth=jnp.linspace(-2,2,20000)**2-1
# Create or split explicit PRNG key(s) (`fresh`) for reproducible randomness.
fresh=truth+.25*jax.random.normal(jax.random.key(95),(20000,))
residual=fresh-truth
assert abs(float(residual.std())-.25)<.01
assert abs(float(residual.mean()))<.01
Correcting the mean removes systematic residual structure in this known simulation; observation noise remains.
Diagnose the result
If the objective has stopped improving, compare to the independent analytic optimum before adding iterations. If parameter uncertainty looks plausible but residuals show a U-shaped trend, investigate the mean model. If only one group is poorly covered, keep group-specific checks instead of relying on aggregate coverage.
Carry forward
- An optimized approximation can still miss posterior covariance.
- Model self-coverage is weaker than evaluation under changed observations.
- Keep inference diagnostics and posterior predictive checks as separate evidence.
Keep your evidence
Analytic and optimized KL, variance comparison, Monte Carlo estimate and explained residual stress fixture. Keep the environment, observed outputs and your explanation of the figure.
Save your modified code, its output, and an explanation of your prediction. Checkpoint answers and exercise evidence are tracked separately.
Saved in this browser. Export or back up your portfolio anytime in My learning.
Verified on local CPU. Stage to a Cloud TPU VM via Cloud TPU setup to record accelerator execution receipts (TODO: add automated Cloud TPU CI execution receipts).
Primary references
Phase 11 Integration Project
Bring this phase together: A Bayesian model with diagnostic evidence
Checkpoint to prove: Report sampler diagnostics and distinguish uncertainty from predictive error.
Copy projects/bayesian-regression/starter/model.py to projects/bayesian-regression/my_model.py and write your code in projects/bayesian-regression/my_model.py. Run python3 projects/bayesian-regression/tests/check.py --implementation projects/bayesian-regression/my_model.py --stage 1 from the top-level folder to verify all 3 stages.